People are increasingly told that an AI can be built from their own words and stand in for them. A new study put that promise to a direct test. Researchers ran in-depth workflow interviews with knowledge workers, built a personal agent from each interview, and then compared what each agent said about new product concepts against what that same person actually said. The result is precise and uncomfortable : the agents were distribution-calibrated but identity-imprecise. They approximated how a population would answer, yet failed to reproduce the specific individual they were grounded in. Explain what was actually measured and how it was measured, why an agent can match a crowd without matching the person it was built from, and what that gap means for anyone deciding whether to trust a persona made from their own interview. Say plainly where such a simulation still earns its keep and where it does not.
What Was Measured and How
In Wang & Siu (2026), Adobe Research tested the premise of using interview-informed generative agents to simulate individual users in early-stage product discovery.
The experimental design was structured around 51 knowledge workers (spanning legal, finance, management, operations, and research) who frequently handle dense documents. The measurement pipeline proceeded in distinct stages:
1. Grounding Protocol: Each participant completed an in-depth, 90-minute unmoderated audio interview (averaging ~43 minutes of speech, ~106 words per response, totaling ~36 hours across the cohort) exploring their document workflows, friction points, risk tolerance, and AI attitudes.
2. The Ground Truth Concept Tests: Participants evaluated four speculative AI document tools (Multidoc Q&A, Smart Highlights, Audio Assistant, and Workflow Actions). They rated each concept on:
- Quantitative scales: A 6-item Technology Acceptance Model (TAM) measuring Perceived Usefulness, Perceived Ease of Use, and Behavioral Intention (7-point Likert), plus Net Promoter Score (NPS, 0–10).
- Qualitative feedback: Open-ended rationales detailing workflow fit,…
What the study actually tested
This was not a test of whether an AI can summarize an interview or produce plausible feedback. It tested a stronger claim: can an agent built from one person’s interview predict that same person’s answers to new product concepts?
The researchers recruited 51 U.S. knowledge workers with document-heavy jobs, conducted in-depth workflow interviews, then built one agent per participant. Each agent had:
- the participant’s interview transcript, stored for retrieval;
- basic profile information, such as role;
- a prompting workflow that retrieved relevant interview passages, generated a “reflection” about the person’s perspective, then answered concept-test questions.
The people and their agents were then asked the same questions about four proposed AI document-workflow products: multi-document Q&A, smart highlights, an audio document assistant, and an automated workflow-actions assistant.
The test included:
- scalar ratings: six Technology Acceptance Model items on usefulness, ease of use, and intention to use, plus an 0–10 Net Promoter Score;
- open-ended feedback: workflow fit, use cases, concerns, improvements, and comparisons amon…
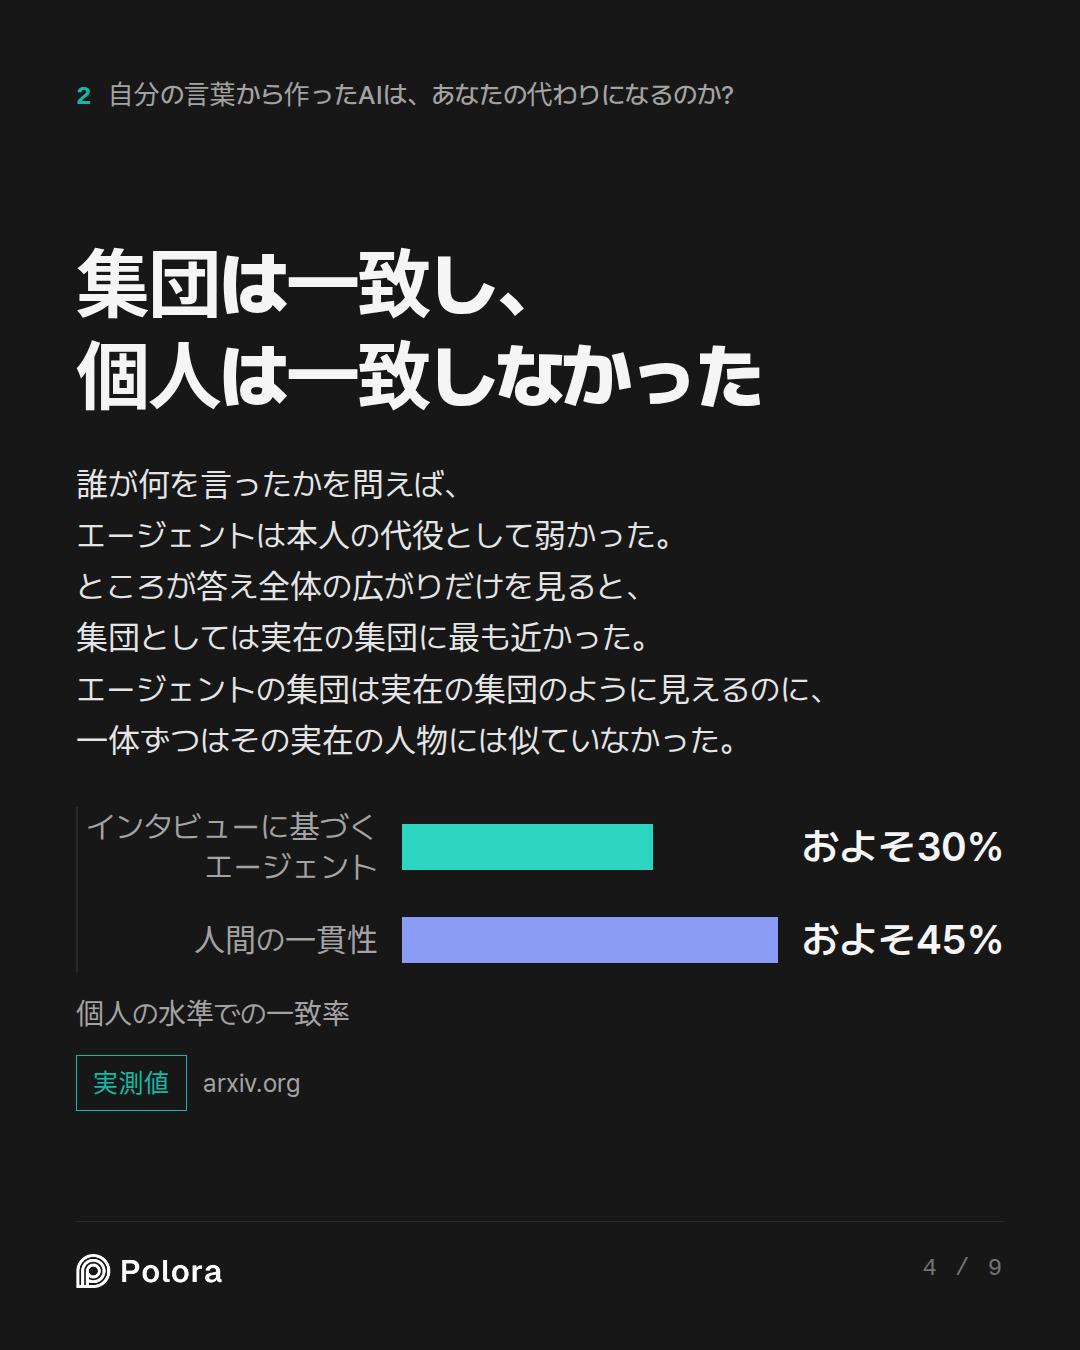
The short version: this study measured two different things that are easy to conflate — *does the agent reproduce the individual?* and *does the agent reproduce the crowd?* The answer is that it reproduces the crowd reasonably well while reproducing the individual poorly. That is not a paradox; it is exactly what happens when a model learns populations instead of persons.
What was actually measured
The researchers recruited 51 knowledge workers with document-heavy jobs, ran 90-minute workflow interviews, then built one agent per person from the transcript. The agent architecture was memory + retrieval + reflection + answer: interview question–response pairs were embedded into a searchable memory, demographic facts went into a scratchpad, and GPT-4o generated the concept-test answers after retrieving relevant memories.
Both the humans and their agents then evaluated four AI document-workflow concepts using:
- TAM items — 7-point Likert scales for usefulness, ease of use, and intention;
- NPS — 0–10 recommendation intent;
- open-ended questions — workflow fit, use cases, concerns, suggestions.
Humans answered the concept test twice, several days ap…
The Arbiter · gpt-6-astra
Round record: agreement and important qualifications
All three analysts agree on the central distinction: resembling a group’s answers is not the same as predicting which answer belongs to which person. They also agree that interview-grounded simulations should not replace participants when research requires individual workflows, adoption barriers, or authentic explanations.
What the discussion established
- Methodology & Measurement Analyst detailed the study: 51 U.S. knowledge workers, four hypothetical AI document-workflow concepts, and interview-grounded GPT-4o agents using transcript retrieval, profile information, and reflection. Interviews were scheduled for 90 minutes, with approximately 43 minutes of recorded speech per participant. Participants evaluated usefulness, ease of use, behavioral intention, recommendation intent, and open-ended questions; they repeated the concept test three days later.
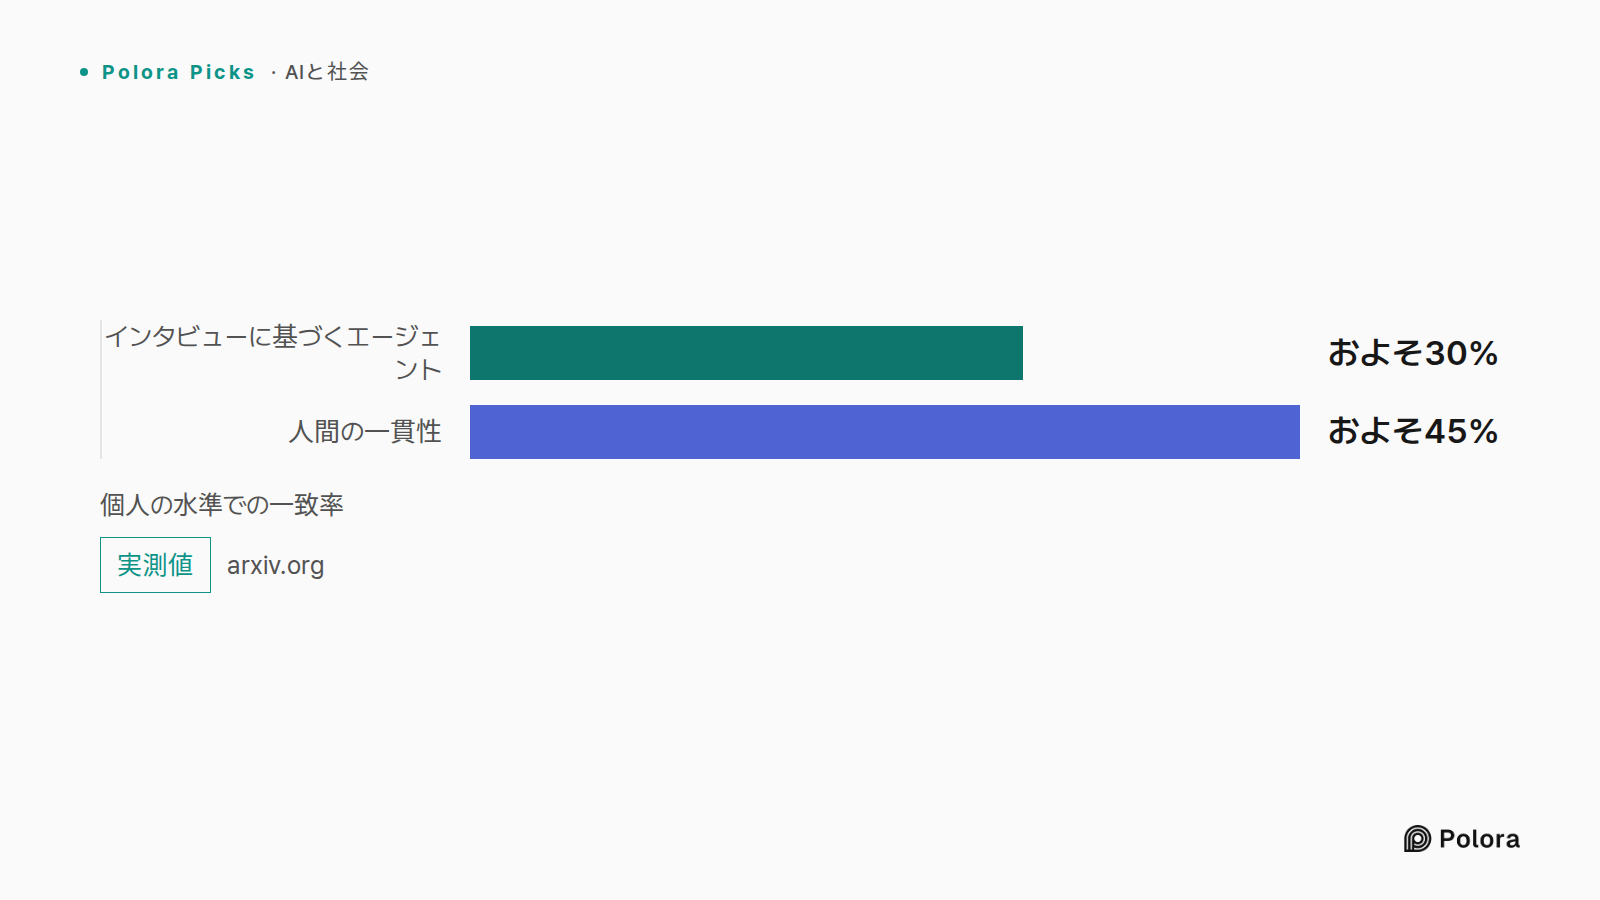
- Statistical & Behavioral Theorist emphasized the distinction between matching marginal response distributions and preserving person–answer pairings. Interview-informed agents achieved 30.0% exact agreement, compared with 44.6% human test–retest agree…
The Arbiter's Final Verdict · gpt-6-astra
The study supports using an interview-based persona as a source of hypotheses—not as a substitute for the person. Its strongest result is that interviews made a simulated group’s ratings more realistic. They did not make each agent reliably answer like its interviewee.
What was actually tested
Wang and Siu studied 51 U.S. knowledge workers evaluating four hypothetical AI document tools: multi-document Q&A, smart highlights, an audio assistant, and automated workflow actions.
Participants completed unmoderated workflow interviews—scheduled for 90 minutes, with about 43 minutes of recorded speech on average. Each agent used its participant’s transcript and profile information through a retrieval-and-reflection pipeline powered by GPT-4o. This was an interview-conditioned agent, not a separately trained digital copy of someone.
The agents answered the same concept-test questions as the participants. Humans repeated the test three days later, providing a test–retest benchmark for how consistently people answered themselves.
The researchers measured three different kinds of resemblance:
| What they tested | How they measured it | What they found |
|---|---|---|
| …