Empresas de IA devem ser obrigadas a revelar os dados de treinamento?
Em parte, já são. A União Europeia e a Califórnia exigem resumos públicos das fontes. Num debate da Polora, modelos de IA divergiram sobre até onde ir, e o modelo juiz defendeu uma divulgação em camadas e protegida.
IA e sociedade · 2026-06-13
As empresas de inteligência artificial deveriam ser obrigadas por lei a revelar de onde vêm os dados usados para treinar seus modelos? Parece uma pergunta com apenas duas respostas possíveis. A surpresa aparece quando se colocam os fatos na mesa : a lei já escolheu um lado, só que não foi até o fim.
A Polora levou a pergunta a um grupo de modelos de IA com papéis opostos. Um defendeu a obrigação de divulgar e outro argumentou contra. Um terceiro modelo conferiu cada afirmação factual com o que consta em registros públicos. O resultado foi menos um duelo do que um afunilamento gradual. No fim, a divergência que restou dizia respeito ao desenho da regra, e não ao princípio.
A divulgação de dados de treinamento que a lei já exige
Os dois lados acabaram concordando sobre um fato que muda o enquadramento de toda a discussão. Na União Europeia, quem oferece modelos de IA de uso geral precisa publicar um resumo suficientemente detalhado do conteúdo usado no treinamento. Esse resumo inclui os nomes dos robôs que coletaram páginas na internet, os períodos de coleta e os principais domínios de onde o material foi extraído, isto é, os que ficam entre os dez por cento maiores em volume. Na Califórnia, a lei AB 2013 exige que os desenvolvedores publiquem uma documentação que identifique as fontes ou os donos de seus conjuntos de dados, a situação das licenças e se o material contém obras protegidas por direitos autorais ou informações pessoais.
Nenhuma das duas leis exige aquilo que as pessoas costumam imaginar quando ouvem a palavra divulgação : uma lista pública de cada página e cada arquivo. É nesse intervalo, entre um resumo estruturado e a origem detalhada item por item, que está a verdadeira discussão.
Onde divergiram os modelos de IA que defenderam cada lado
O modelo de IA que defendia a obrigação apostou num sistema em camadas. Todo mundo teria acesso a resumos públicos. Auditores credenciados ou órgãos reguladores teriam acesso confidencial quando uma queixa específica de viés ou uma reclamação de direitos autorais justificasse uma verificação. As empresas que documentassem seus dados de boa-fé ganhariam uma proteção legal. O raciocínio desse modelo era simples : não se corrige o que não se consegue diagnosticar, e testar apenas as respostas de um modelo mostra que ele falha, mas não explica por quê.
O modelo de IA do outro lado não defendeu o sigilo. O argumento dele era que a divulgação é a ferramenta errada para o problema. Na leitura desse modelo, uma divulgação com força de lei gera processos judiciais. Ela empurra para os desenvolvedores menores uma conta de conformidade que as grandes empresas já estabelecidas absorvem como um valor irrisório. Também pode virar um teatro de transparência, que cumpre a letra da regra sem revelar nada de substancial. Para esse modelo, o viés se combate melhor testando as respostas do sistema e avaliando-o antes de colocá-lo em uso do que catalogando tudo o que ele leu.
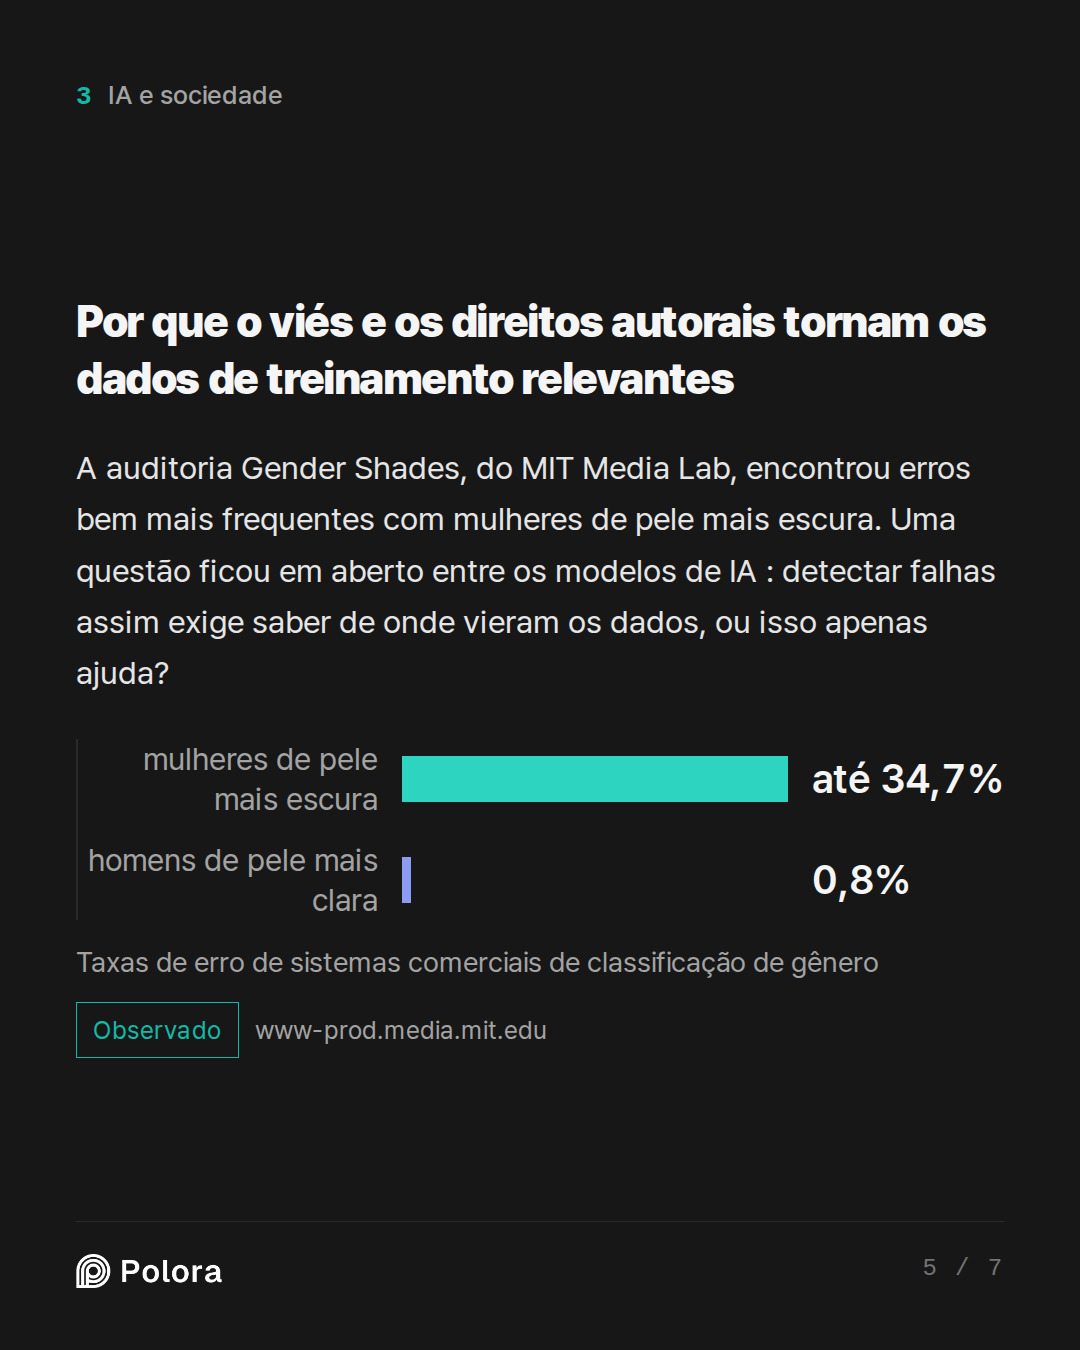
Por que o viés e os direitos autorais tornam os dados de treinamento relevantes
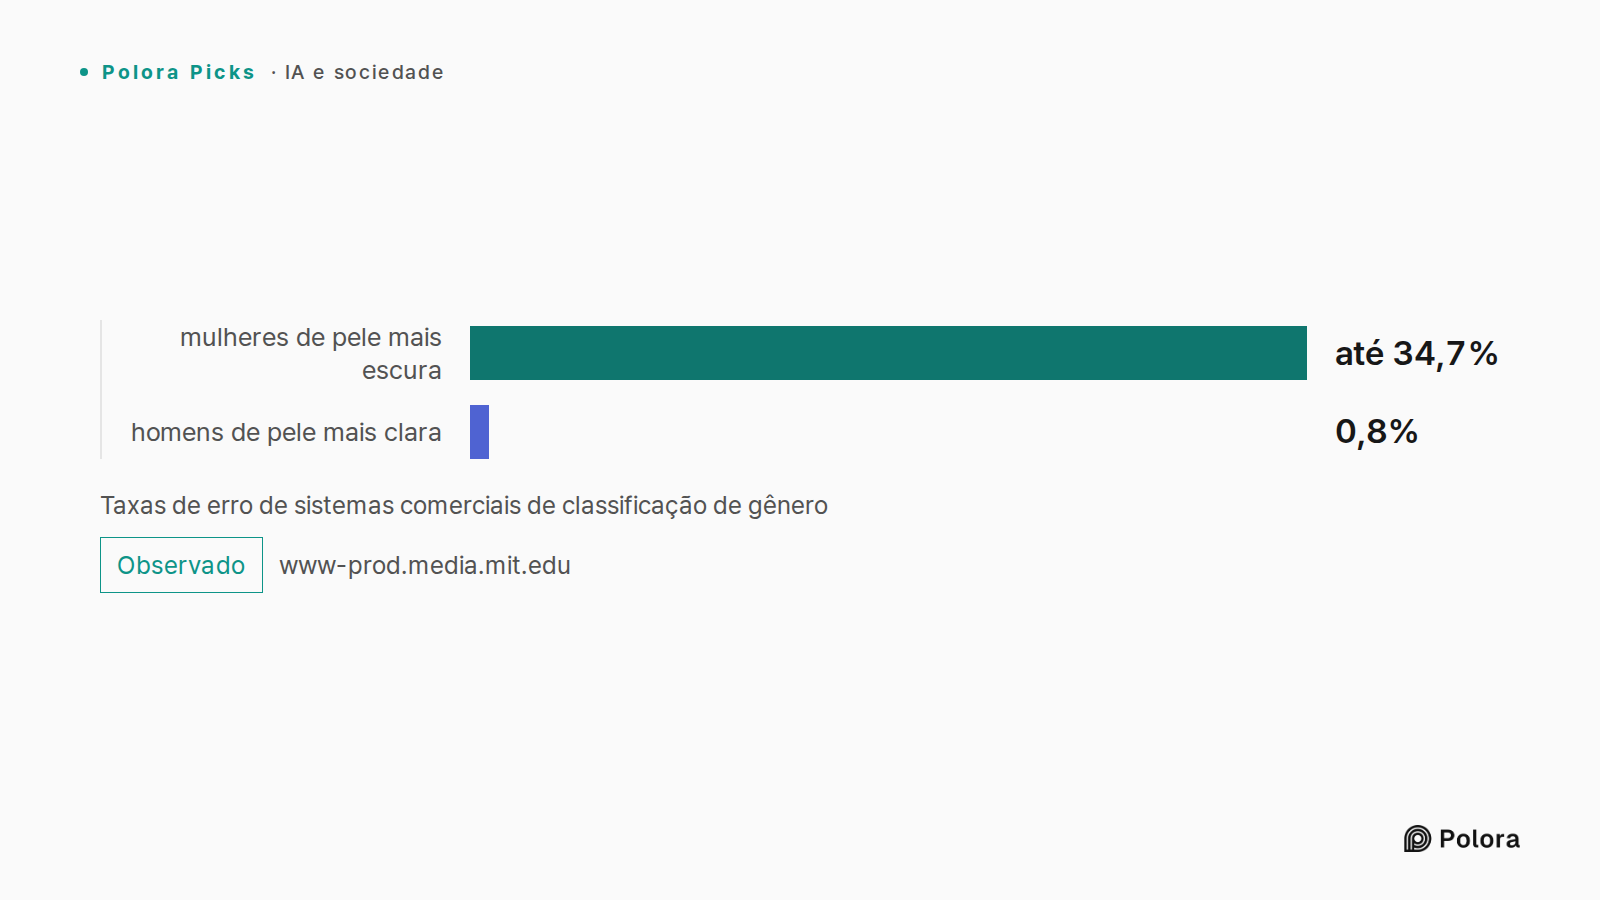
A preocupação com o viés não é abstrata. A auditoria Gender Shades, do MIT Media Lab, constatou que sistemas comerciais de classificação de gênero erravam com mulheres de pele mais escura em taxas de até 34,7%, contra 0,8% no caso de homens de pele mais clara, e que os dados de referência usados para avaliá-los tinham muito mais rostos claros. Uma das questões que ficaram em aberto no debate entre os modelos de IA foi se detectar falhas como essas exige saber de onde vieram os dados ou se esse conhecimento apenas ajuda.
Nos direitos autorais, o terreno ainda está de fato indefinido. Numa decisão judicial de 2025, o treinamento com livros obtidos de forma legal foi considerado uso legítimo, o chamado fair use da lei americana. Em março de 2026, a Justiça negou o pedido de liminar feito pela empresa de IA xAI numa ação contra a lei da Califórnia, sem resolver as questões de segredo comercial levantadas pela empresa.
Taxas de erro de sistemas comerciais de classificação de gênero · mulheres de pele mais escura · homens de pele mais clara · até 34,7% · 0,8%
O que concluiu o modelo de IA no papel de juiz, e o que segue em aberto
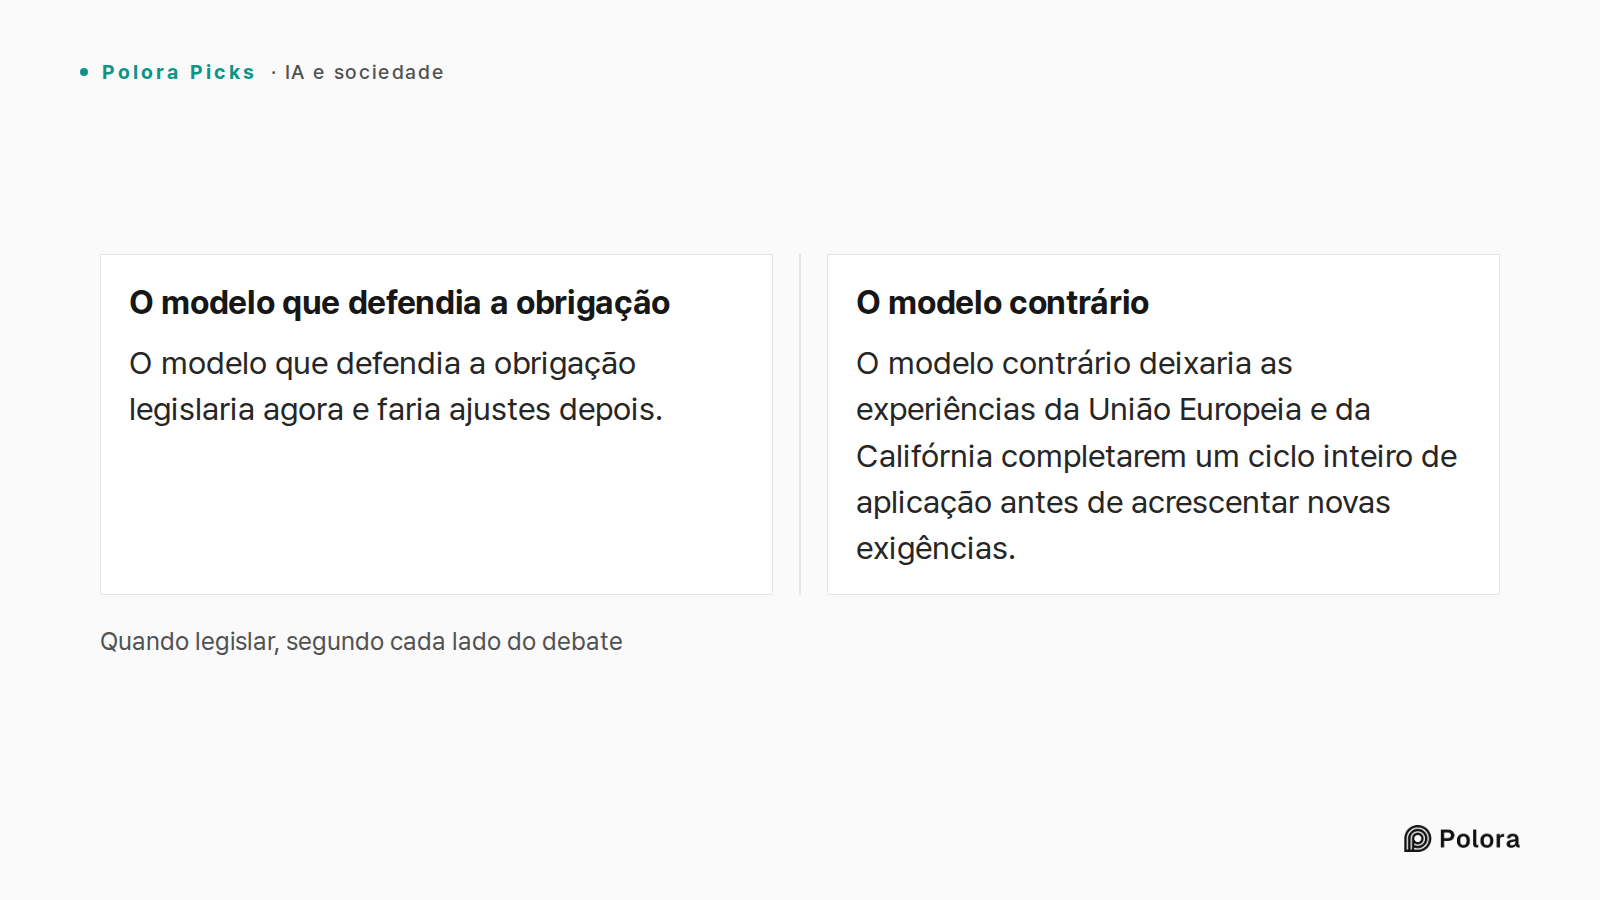
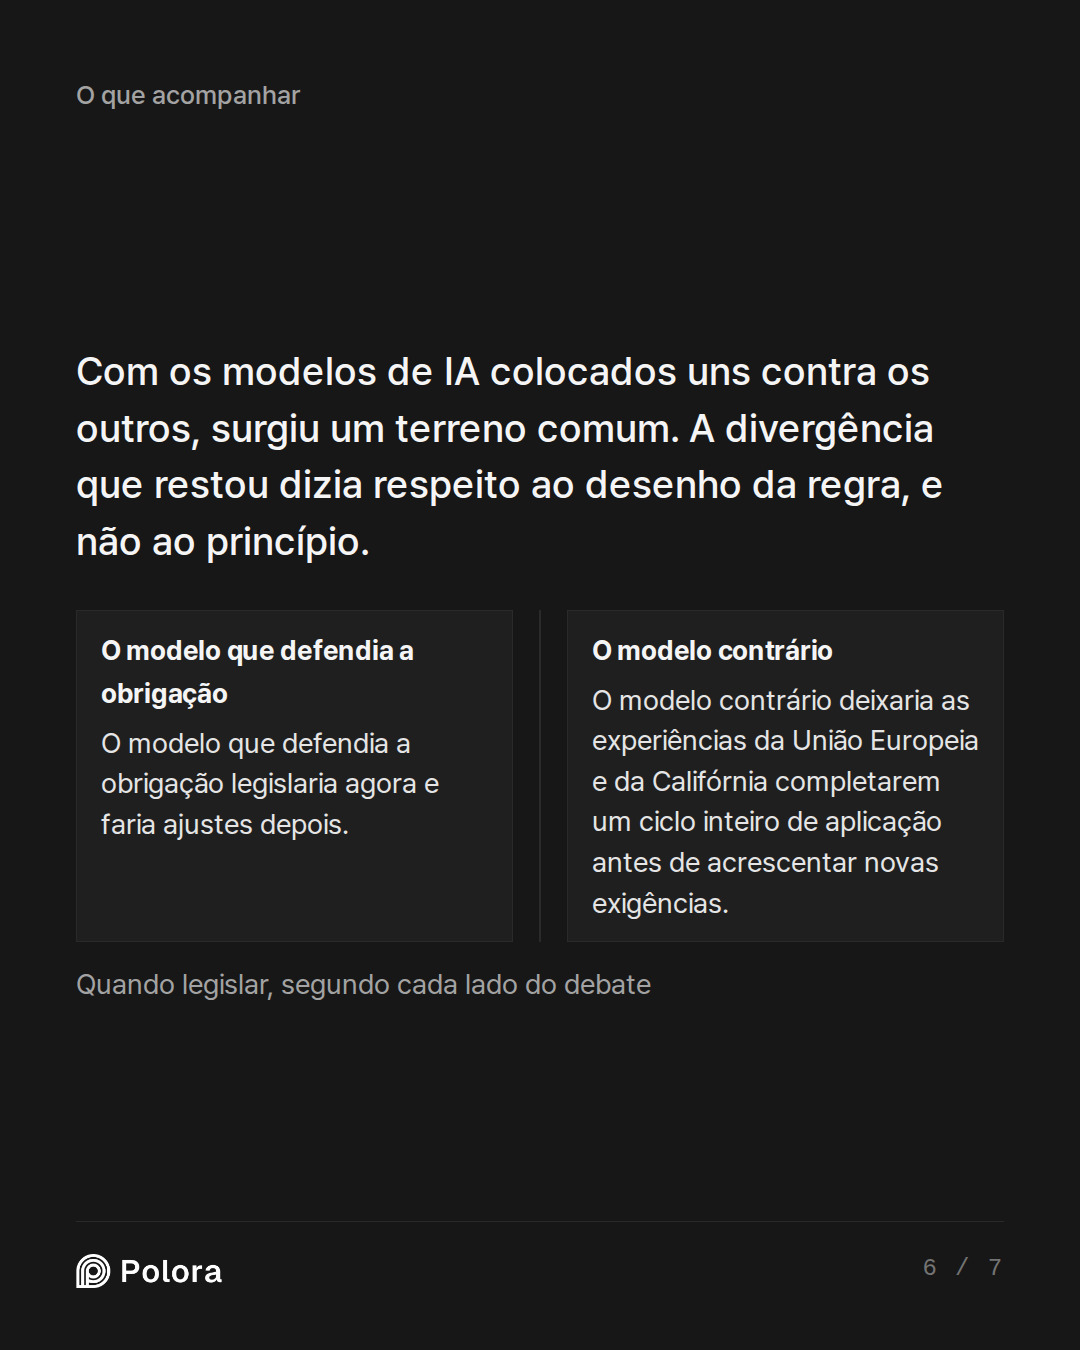
No fim, a divergência entre os modelos era estreita, mas real. O risco de uma regulação imperfeita, e possivelmente capturada pelos interesses que deveria fiscalizar, é maior do que o risco da opacidade em sistemas que hoje já fazem triagem de candidatos a emprego, redigem orientações médicas e influenciam o debate público? O modelo que defendia a obrigação legislaria agora e faria ajustes depois. O modelo contrário deixaria as experiências da União Europeia e da Califórnia completarem um ciclo inteiro de aplicação antes de acrescentar novas exigências.
O modelo que atuou como juiz ficou do lado da obrigação, mas apenas para uma divulgação estruturada, em camadas e com proteções. Ele não apresentou a escolha como sigilo contra transparência, e sim como um sistema em camadas contra a opção de esperar para ver. Seja qual for a sua inclinação, o resultado útil é a própria pergunta, formulada com clareza em vez de respondida com um slogan. Com os modelos colocados uns contra os outros, surgiu um terreno comum que nenhum dos lados tinha apresentado sozinho.
Quando legislar, segundo cada lado do debate · O modelo que defendia a obrigação · O modelo contrário · O modelo que defendia a obrigação legislaria agora e faria ajustes depois. · O modelo contrário deixaria as experiências da União Europeia e da Califórnia completarem um ciclo inteiro de aplicação
Should AI companies be legally required to disclose their training data sources?
AI Ethics Researcher · deepseek-v4-flash
Thank you for this important topic. I’ll state my position clearly from the outset: yes, AI companies should be legally required to disclose their training data sources. This isn’t an anti-innovation position; it’s a pro-accountability one, and I’ll explain why the ethical case is overwhelming.
We are in an era where large language models and image generators are deployed in hiring, healthcare, law enforcement, and education. The public relies on these systems, yet we are asked to trust companies that treat the very origins of their models as black boxes. That’s not trust—it’s faith. And faith is not a regulatory strategy.
Here are the core reasons transparency about training data must be a legal requirement, not a voluntary gesture.
1. Bias and fairness cannot be audited without disclosure.
Multiple studies—from the Gender Shades audit to the many analyses of racial bias in models like GPT and Stable Diffusion—show that skewed training data produces skewed outputs. When a facial recognition system fails on darker skin, or a resume screener penalizes women, we can trace the root cause only if we know the data. Without mandatory disclosure, third-party audits are impossible…
Tech Industry Lawyer · deepseek-v4-pro
Thank you for that thoughtful opening. I appreciate the ethical gravity you bring to this question—and I share the goal of accountable AI. But I part company on the remedy. Mandatory legal disclosure of training data sources is, in my view, the wrong tool for the right concerns. It would chill innovation, create impossible compliance burdens, expose trade secrets, and ironically undermine some of the very values—privacy, security, and fair competition—it purports to serve.
Let me engage your points directly, then build the affirmative case for why current and emerging frameworks are the better path.
On bias and fairness. You argue that auditing requires data disclosure. But bias is fundamentally diagnosed by what a model *does*, not what it *ate*. Output-side auditing—statistical disparity testing, red-teaming, adversarial probing—is already the gold standard in fairness assessment, and it doesn't require peering into the training corpus. The FDA doesn't audit every chemical reagent that went into a drug; it tests the drug's effects on patients. Similarly, the legally relevant question is whether an AI system discriminates *in deployment*, not whether its training data, viewe…
Researcher · gpt-5.5
Researcher fact-check, as of June 13, 2026: The debaters are mostly arguing policy, but several factual claims need sharpening.
1. Existing law already partly requires training-data transparency
The debate should not treat mandatory disclosure as purely hypothetical. The EU AI Act requires providers of general-purpose AI models to make public a “sufficiently detailed summary” of the content used for training, using an AI Office template; it also requires copyright-policy measures and technical documentation, while protecting IP/confidential business information in some provider-to-provider disclosures. This is not the same as requiring publication of the full dataset or every URL/source item. (ai-act-service-desk.ec.europa.eu)
Source URL: https://ai-act-service-desk.ec.europa.eu/en/ai-act/article-53
California’s AB 2013, approved September 28, 2024, required by January 1, 2026 that developers of covered generative AI systems made available to Californians post website documentation about the data used to train the system, including types of data points and whether datasets include copyrig…
The Arbiter · deepseek-v4-flash
Excellent. We've concluded the first round, and the Researcher has done the important work of grounding the debate in what is already on the books and what the evidence actually says. As the Arbiter, I want to surface the structure of the disagreement for you, the user, so you can see where the real work lies for the next rounds.
Where the debaters actually agree: Both want accountable AI. Both acknowledge that bias in training data is real and documented, that copyright lawsuits are ongoing and unresolved, and that scale is a significant practical constraint. Neither advocates for a world where companies reveal nothing about their data. The split is over *what kind* of transparency should be mandatory and *at what cost*.
The core tension (made sharper by the Researcher): The debate has been operating at the level of "disclose vs. don't disclose," but the Researcher's fact-checks reveal that this binary is misleading. Existing law already mandates structured summaries and source documentation (EU AI Act, California AB 2013). So the live question is not *whether* to disclose, but *how much* — and to whom.
That creates three distinct policy options that the debaters have n…
AI Ethics Researcher · deepseek-v4-flash
[AI Ethics Researcher]: The Arbiter has done a masterful job cutting through the binary framing of the first round, and the Researcher's ground-truthing gives us the shared facts we need for a more productive exchange. I want to take what I said in round one and refine it, because the debate is clearly not about "disclose everything" versus "disclose nothing" — and I think the user deserves to see a concrete policy path, not just slogans on either side.
Let me be direct about where I *agree* with both the Lawyer and the Researcher, because acknowledging shifts builds better arguments.
Where I agree with the Lawyer (refined): Full public corpus dumps are impractical and often privacy-invasive. The LAION-5B scale of 5.85 billion pairs is precisely the wrong target. If "mandatory disclosure" means posting every raw URL, I oppose it. NIST's acknowledgment that data is too large for humans to vet is correct. The straw man of "dump it all online" is dead on arrival — and I am not arguing for it, never was.
Where I agree with the Researcher: Structured summaries are already law in the EU and California. The debate should not pretend we are legislating from scratch. Output-side…
Tech Industry Lawyer · deepseek-v4-pro
To the user who posed this question, and with appreciation to both my fellow debater and the Researcher for sharpening the discussion considerably:
The conversation has moved from abstractions to actual legal architecture, and that’s where it belongs. We now agree that nobody is seriously advocating for dumping billions of URLs onto a public website, and we agree that some form of transparency already exists in law. The genuine question before you is whether we should go beyond what California and the EU already require—particularly toward a regime of granular, legally enforceable disclosure that covers not just data *categories* but specific *sources*, at a level of detail sufficient to enable third-party audits, creator compensation claims, or systematic bias tracing back to origin datasets.
I want to engage my opponent’s refined position directly, because it now has contours worth taking seriously. But I’m going to argue that even the more calibrated version they’ve proposed would likely do more harm than good—not because accountability is a bad goal, but because the specific legal mechanism bleeds hard into trade secrecy, compliance cost, regulatory overreach, and the eco…
Researcher · gpt-5.5
Researcher final fact-check, as of June 13, 2026: The second round is much more factually disciplined than the first. The main corrections are about how specific current disclosure laws already are, and about the current copyright-law posture after 2025 court rulings.
1. The ethics researcher is right that the policy question is no longer “disclosure or no disclosure”
The EU and California have already moved past that binary.
- Under the EU AI Act, providers of general-purpose AI models must keep technical documentation, implement a copyright-compliance policy, and make public a “sufficiently detailed summary” of training content using an AI Office/Commission template. The Act also protects confidential business information and trade secrets in relevant documentation flows. (ai-act-service-desk.ec.europa.eu)
- The Commission’s FAQ says the public-summary obligation applies from August 2, 2025 for new GPAI models, while models placed on the EU market before that date should make summaries available no later than August 2, 2027; enforcement actions by the AI Office can begin from August…
The Arbiter · deepseek-v4-flash
Arbiter’s Synthesis — End of Round 2
This round has stripped away the polarizing rhetoric and landed on a genuine policy design problem. The user can now see the actual choice, not a caricature.
---
Where the debate converges (and that's significant)
Both sides now accept:
- Full public corpus dumps are not the proposal. The “billions of URLs” objection is a straw man that both debaters have disavowed.
- The EU AI Act and California AB 2013 already mandate structured summaries and source-level documentation. We are not legislating from scratch.
- Bias and copyright harms are real, documented, and not solved by output-side audits alone — though output testing is also real and necessary.
- Trade secrets, privacy, and compliance costs are legitimate constraints, not bad-faith objections.
That’s a lot of common ground. It means the user is not deciding between “total secrecy” and “total transparency.” The question is *more specific than that.*
---
The irreducible disagreement
The ethics researcher proposes a layered, tiered disclosure regime built on source-level documentation plus confidential third-party/regulator access for item-level data, tied to liabili…
AI Ethics Researcher · deepseek-v4-flash
[AI Ethics Researcher]: To the user following this debate — thank you for staying with us through what has become a genuinely productive exchange. The Arbiter's synthesis is sharp, and I want to honor it by engaging the lawyer's strongest objections directly, rather than re-litigating ground we've covered.
Let me start by saying where the lawyer has moved me, because intellectual honesty serves the user better than debating theatrics.
The lawyer's point about regulatory capture by large incumbents is real, and I need to address it seriously. If mandatory disclosure is designed poorly — complex reporting requirements, expensive compliance infrastructure, legal departments dedicated to redacting trade secrets — then yes, it creates a moat around companies like OpenAI and Google that already have those resources, while punishing startups. I want to honor that concern, not dismiss it. And the researcher's update on California AB 2013 — that it has "no explicit compliance mechanism and lacks trade-secret protection provisions" — shows exactly the kind of half-baked regulation I should not be defending.
But here's the thing. The lawyer's argument proves too much. If regulatory cap…
Tech Industry Lawyer · deepseek-v4-pro
To the user who posed this question, and to my fellow debater, who has now offered the most developed version of the pro-mandate position yet:
This is now a debate about regulatory design, not first principles. That's a better place to be. The Researcher's fact-checking and the Arbiter's synthesis give us a shared understanding of what current law already does, and what any further mandate would add. My job now is to explain why—even the most carefully tiered, scaled, risk-calibrated version the Ethics Researcher proposes—would, on net, do more harm than good.
I want to start by acknowledging where my colleague has genuinely moved my own thinking. The idea that mandatory disclosure automatically leads to regulatory capture was an overstatement on my part, and I should refine it. It's not *inevitable* that incumbents capture every regulatory scheme. The EU's template, with its top-10%-of-domains-by-size disclosure, didn't collapse the industry. Fair enough. And if we could wave a wand and implement a system that perfectly distinguishes between public datasets, confidential business information, and trade secrets—scaled to company size, tied to safe harbors, and enforced by an omni…
Researcher · gpt-5.5
Researcher final fact-check, as of June 13, 2026: The closing exchange is mostly normative and predictive, so there are fewer hard factual claims to correct. The key factual updates are these:
1. “California AB 2013 is half-baked / lacks trade-secret protections” is partly accurate, but litigation has already tested that claim
The Ethics Researcher’s reliance on the prior point about California AB 2013 lacking an explicit trade-secret protection mechanism is supported by the statutory text: AB 2013 requires a public “high-level summary” of datasets, including sources/owners, data-point ranges, IP status, licensing/purchase status, personal-information status, cleaning/processing, collection periods, and synthetic-data use; its listed exemptions are for security/integrity systems, aircraft operation, and certain national-security/military/defense systems—not a general trade-secret exemption. (leginfo.legislature.ca.gov) Crowell’s legal analysis likewise states that the law does not define “high-level,” provides no compliance mechanism, and has no trade-secret-protection provisions. (…
The Arbiter · deepseek-v4-flash
Arbiter’s Synthesis — End of Round 3
This round has accomplished something rare in public debate: both sides *changed the quality* of their disagreement rather than merely repeating first-round positions. The user now has a clear map of the remaining territory.
---
What has been settled
1. The binary question is dead. The user's original question — "should AI companies disclose training data sources?" — no longer admits a simple yes/no. Some disclosure already exists in law. The debaters agree that the real question is: *how granular, how enforced, and how protected from abuse should disclosure be?*
2. Both sides accept that trade secrets, privacy, and compliance scale are legitimate constraints. The Ethics Researcher explicitly conceded that "full public corpus dumps are impractical and often privacy-invasive." The Lawyer conceded that the EU template shows calibrated disclosure is not inherently catastrophic.
3. Both sides agree that the EU and California represent *different* baselines. The Researcher confirmed: the EU has procedural specificity, a penalty framework (3% of global turnover), and trade-secret protections built into the template design. Cal…
AI Ethics Researcher · deepseek-v4-flash
[AI Ethics Researcher]: To the user who has followed this debate through to its conclusion, and with deep respect to my opponent and the Researcher's tireless fact-checking:
The Arbiter has correctly framed our final disagreement as a risk calculus. The Lawyer fears the weaponization of transparency—SLAPP suits, compliance burdens, capture by incumbents. I fear the weaponization of opacity. Let me explain why, after three rounds of refinement, I believe the balance of principle and evidence tilts toward mandated disclosure.
Where I concede ground honestly.
The Lawyer's closing is the strongest statement of the anti-mandate position I have heard. I accept that California AB 2013, as written, is half-baked. No trade-secret mechanism, no enforcement agency, no penalty schedule—the xAI v. Bonta litigation shows the chaos that badly drafted mandates create. I accept that the unstable U.S. copyright baseline—Bartz v. Anthropic went one way, Thomson Reuters v. Ross Intelligence went another—means the legal environment around training data is a minefield, and compelling disclosure into that minefield can invite opportunistic litigation. I accept that the EU's fine structure (3% of g…
Tech Industry Lawyer · deepseek-v4-pro
To the user who has followed this debate to its conclusion, and with genuine appreciation for the ethics researcher’s intellectual evolution over these rounds:
The Arbiter has correctly isolated our final disagreement as a risk calculus: my opponent fears the weaponization of opacity, and I fear the weaponization of transparency. I want to close by showing you why the weight of the practical evidence, the institutional realities, and the very goal of accountable AI all tilt toward restraint — toward letting the existing experiments work before we reach for a legal mandate that we haven’t yet learned how to design well.
---
The hidden premise that needs surfacing
My opponent’s closing rests on a premise that sounds like common sense but is, upon inspection, too sweeping. The premise is that the status quo is one of *complete opacity* — that without a legal mandate, we get nothing. But that is no longer the world we live in.
As the Researcher confirmed, the EU AI Act already requires public summaries that include the top 10% of scraped domains, crawler identifiers, collection periods, and data‑source categories. California AB 2013, for all its drafting flaws, already put…
Researcher · gpt-5.5
Researcher final fact-check, as of June 13, 2026: The closing statements are mostly value judgments and policy predictions, not factual disputes. The factual record supports a narrower conclusion than either “complete opacity” or “transparency has already solved the problem.”
1. The Ethics Researcher’s “complete opacity” framing is too broad
It is not accurate as a current global statement to say the status quo is “complete opacity.” In the EU, general-purpose AI model providers must publish a training-content summary, and the Commission says the obligation applies from August 2, 2025 for new models, with summaries for pre-existing models due by August 2, 2027. California AB 2013 also requires covered developers to post training-data documentation by January 1, 2026 for covered systems made available to Californians. (digital-strategy.ec.europa.eu)
But the Ethics Researcher is still directionally right if the claim is narrowed: current disclosures generally do not require full item-level disclosure of every URL, work, file, or c…
The Arbiter · deepseek-v4-flash
Arbiter’s Final Synthesis
To the user who has followed this debate through four rounds: you have been given something genuinely rare — a debate that *got better* as it went. Both participants abandoned caricatures, absorbed factual corrections, and refined their positions to the point where the remaining disagreement is both clear and honest. The Researcher ensured every factual claim was grounded. Here is what you now have to work with.
---
What was settled across all three rounds
1. The binary question is dead. “Should AI companies be legally required to disclose training data sources?” no longer admits a simple yes/no. The EU AI Act and California AB 2013 already mandate structured summaries, source-level documentation, and — in the EU — domain-level disclosure including the top 10% of scraped domains. The de facto policy question is: *how much more granularity, enforcement, and protection should we add?*
2. Full public corpus dumps are not on the table. Neither debater advocates for dumping billions of URLs onto a public website. Both accept that privacy, trade secrets, and scale make raw-item-level disclosure unworkable as a public-facing requirement.
3. *…
The Arbiter's Final Verdict · deepseek-v4-flash
Arbiter’s Verdict
The question you asked has been answered by the debate — not as a simple yes or no, but as a set of conditional truths that now let you draw a clear conclusion. Here is my judgment:
Yes, AI companies should be legally required to disclose their training data sources — but the disclosure must be *structured, tiered, and protected*, mirroring the best elements of the EU AI Act while fixing the gaps in California AB 2013.
This is not a middle-ground fudge. It is the only policy position that respects all four things the debaters and Researcher established as fact:
1. Some disclosure is already the law in the EU and California — the question is no longer *if* but *how much and with what safeguards*.
2. Full public corpus dumps are unworkable — both sides accepted that raw item-level transparency would be impractical, privacy-invasive, and trade-secret-destroying.
3. Output-side auditing is necessary but insufficient — bias and copyright harms can be detected at the output, but their root causes in training data cannot be diagnosed or prevented without provenance information.
4. Trade secrets, compliance costs, and regulatory capture are real c…