그렇습니다. 더 잘하는 경우도 많습니다. 몸집이 훨씬 작은 전문 모델이 몇 배 큰 모델들보다 동물을 훨씬 정확하게 알아봤고, 큰 모델들은 이따금 존재하지 않는 종의 이름을 지어냈습니다. 인터넷이 닿지 않는 야외 카메라에 얹을 만한 모델들을 견준 연구의 결과입니다.
해설 대상 : Can Edge-Deployable Vision-Language Models Identify Species?, William Zhou et al., 2026-09-10, v1 원문 보기
AI와 사회 · 2026-09-13
야생 보호구역의 나무에 붙은 카메라는 무언가 앞을 지나갈 때마다 사진을 찍습니다. 그리고 이제는 점점 더 많은 카메라가 기기 안에서 돌아가는 작은 AI 모델을 써서 스스로 동물의 이름을 맞히려 합니다. 야외에서는 사진을 어디론가 보낼 신호가 잡히지 않는 곳이 많기 때문입니다. 그래서 단순한 물음이 뒤따릅니다. 카메라에 얹힐 만큼 작은 모델이 정말 자기가 무엇을 보고 있는지 알 수 있을까요?
최근의 한 연구가 바로 그 물음에 답하려고, 야외 카메라에서 돌아갈 만큼 작은 모델들이 눈앞의 동물을 얼마나 잘 알아보는지 쟀습니다. 결과는 불편하지만, 그래서 오히려 쓸모가 있습니다. 살펴본 모델들은 동물에 대한 진짜 지식을 갖고 있었습니다. 그런데 그보다 훨씬 작은 전문 모델이 그들 모두를 이겼고, 그 모델들은 이따금 한 번도 존재한 적 없는 종의 이름을 답으로 내놓았습니다.
폴로라는 이 논문을 여러 회사가 만든 AI 모델들에게 건네주고, 야외에서 무언가를 알아보는 데 작은 모델에 기대는 사람에게 이것이 무슨 뜻인지 함께 짚어 보게 했습니다. 아래 글은 그 논문과 그 논의에 기댑니다.
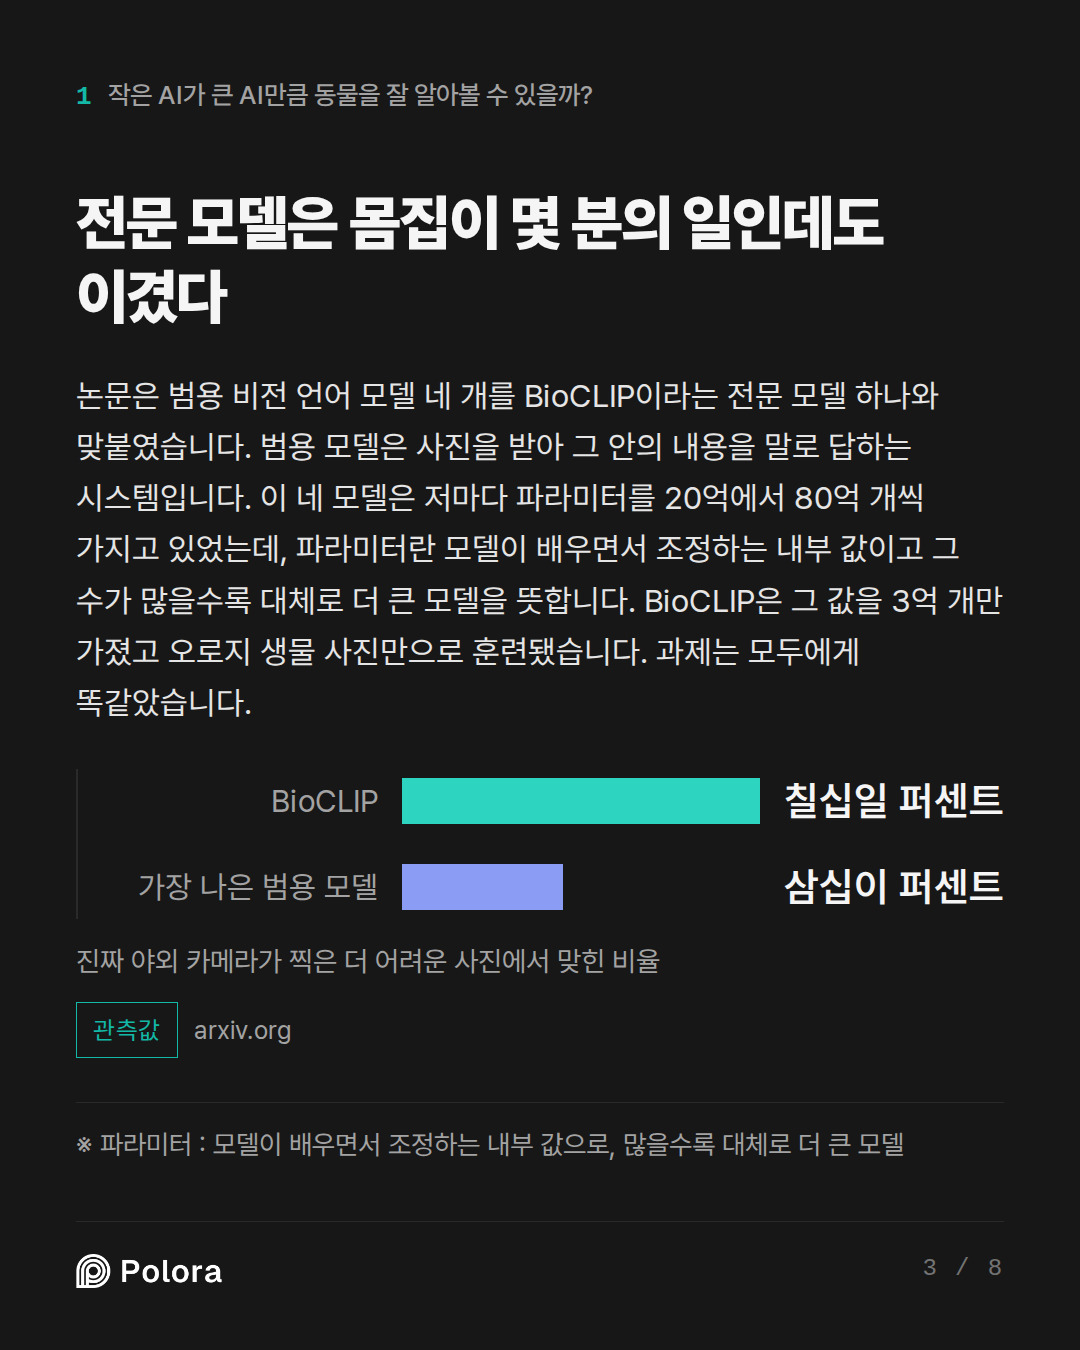
논문은 범용 비전 언어 모델 네 개를 BioCLIP이라는 전문 모델 하나와 맞붙였습니다. 범용 모델은 사진을 받아 그 안의 내용을 말로 답하는 시스템입니다. 이 네 모델은 저마다 파라미터를 20억에서 80억 개씩 가지고 있었는데, 파라미터란 모델이 배우면서 조정하는 내부 값이고 그 수가 많을수록 대체로 더 큰 모델을 뜻합니다. BioCLIP은 그 값을 3억 개만 가졌고 오로지 생물 사진만으로 훈련됐습니다. 과제는 모두에게 똑같았습니다. 사진을 보고 96종 가운데 맞는 종을 고르는 것이었습니다.
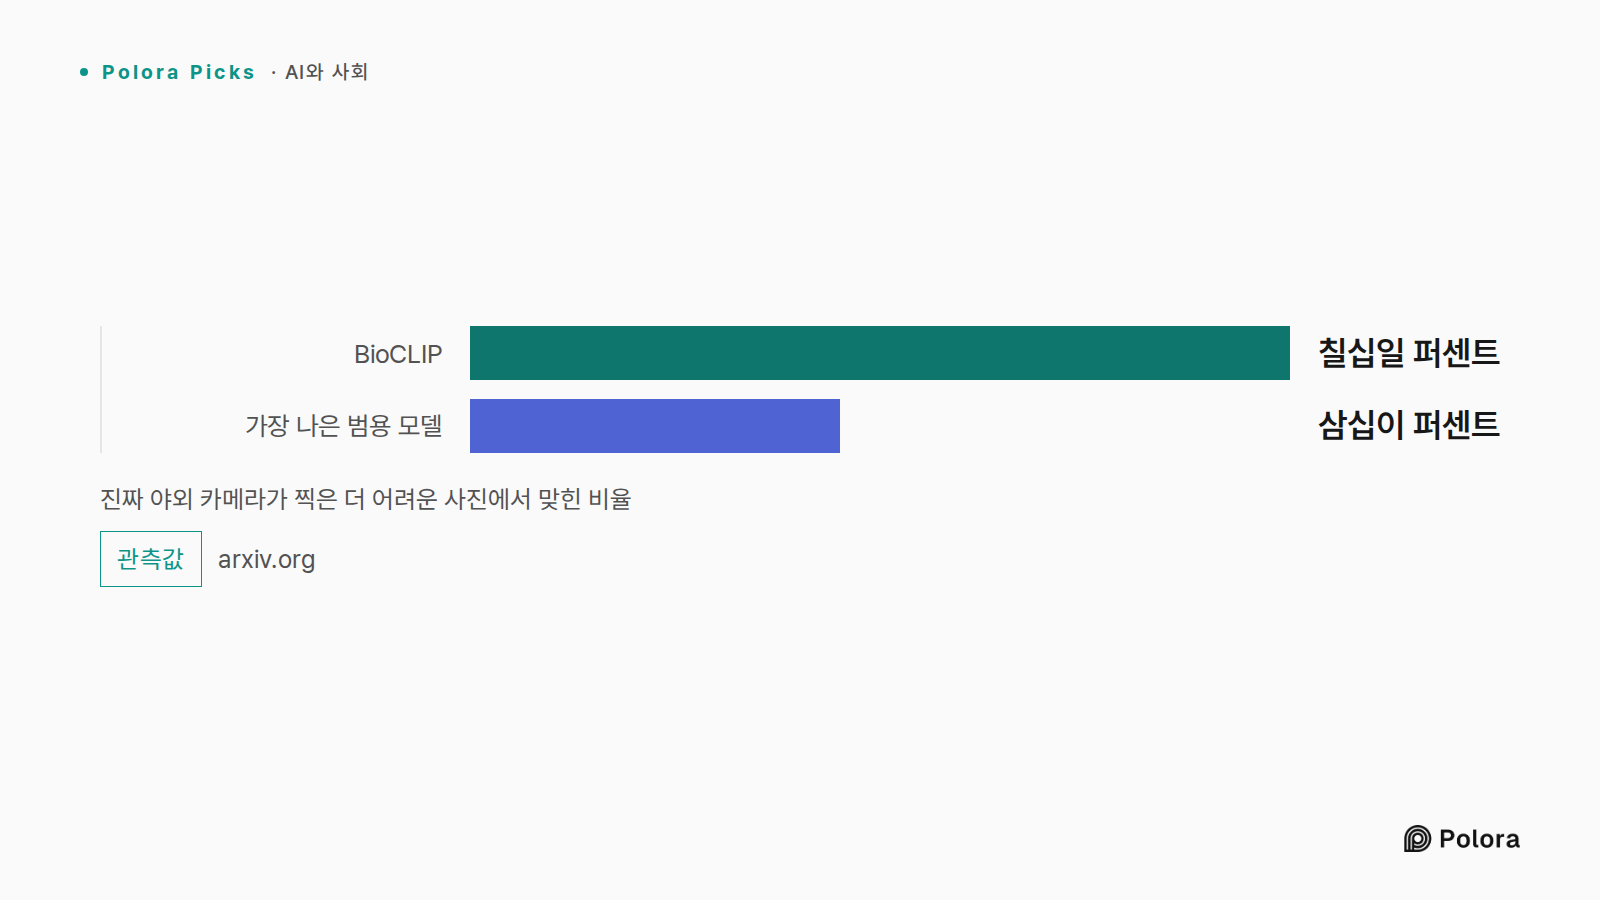
깨끗한 표준 사진에서는 BioCLIP이 약 구십 퍼센트를 맞혔고, 범용 모델 가운데 가장 나은 것은 오십육 퍼센트쯤에 그쳤습니다. 진짜 야외 카메라가 찍은 더 어려운 사진에서도 격차는 그대로였습니다. BioCLIP은 칠십일 퍼센트, 가장 나은 범용 모델은 삼십이 퍼센트였습니다. BioCLIP은 경쟁 상대보다 몸집이 일곱에서 스무 배 작으면서 이 일을 해냈습니다.
논문은 이를 크기가 아니라 훈련에 대한 교훈으로 읽습니다. 차이를 만든 것은 파라미터가 더 많아서가 아니라, 전문 모델이 잘 골라 모은 생물 사진 묶음을 공부했다는 점이었습니다. 게다가 전문 모델은 돌리는 데 훨씬 쌌습니다. 한 장에 약 반 초 만에 답한 반면, 파라미터 80억 개짜리 모델은 보통 사진 한 장에 십팔 초쯤, 평균으로는 삼십 초가 걸렸고, 가장 느릴 때는 일 분을 훌쩍 넘겼습니다. 배터리나 태양광 패널로 돌아가는 카메라에서 그 속도는 한 철 내내 지켜보느냐 죽은 기기가 되느냐를 가릅니다.
진짜 야외 카메라가 찍은 더 어려운 사진에서 맞힌 비율 · BioCLIP · 가장 나은 범용 모델 · 칠십일 퍼센트 · 삼십이 퍼센트
가장 눈에 띈 실패는 고를 목록 없이 열린 물음을 던졌을 때, 그러니까 이 종의 이름을 대라고 했을 때 나왔습니다. 그 답의 약 육에서 십 퍼센트는 꼴은 그럴듯한 학명이지만 실제로는 어떤 동물에도 붙지 않는 이름이었습니다. 막혔을 때 모델들은 입을 다물지 않았습니다. 존재하지 않는 생물에 대해 자신 있고 그럴듯해 보이는 이름을 만들어 냈습니다.
이 버릇은 무작위가 아니었습니다. 모델 가운데 Gemma3 4B는 다른 어느 모델보다 세 배에서 여덟 배 더 자주 이름을 지어냈고, 이 순위는 서로 다른 두 시험 묶음에서 똑같이 유지됐습니다. 그래서 이것은 어느 한 수치보다 탄탄한 결과입니다. 연구진은 모든 답을 세계의 알려진 종을 담은 확립된 목록과 대조해 진짜 이름과 지어낸 이름을 가려냈습니다.
폴로라가 한자리에 불러 모은 AI 모델 가운데 하나가 평가 분석가 역할로 여기서 선을 분명히 그었습니다. 자주 맞히는 것과 믿을 만한 것은 같지 않다는 것입니다. 망설여야 할 때 자신 있게 답하는 모델은, 그저 점수가 낮은 모델보다 자동화된 시스템 안에서 더 위험합니다. 뒤에 이어지는 어떤 것도 좋은 답과 유창한 억측을 가려낼 수 없기 때문입니다.
그러면 전문 모델이 그냥 안전한 선택이라고 결론지어 버리기 쉽습니다. 하지만 논문은 그렇게 단정하지 못하게 합니다. BioCLIP을 포함한 모든 모델이 깨끗한 사진에서 야외 사진으로 넘어가면서 정확도를 크게 잃었습니다. 야외 사진은 흐릿하고, 야간 적외선으로 찍혔고, 동물이 화면에 반쯤만 걸린 것들입니다. BioCLIP의 하락 폭은 가장 나은 범용 모델의 하락 폭과 통계적으로 구별되지 않았습니다.
이 결과는 탓을 모델보다 사진에 돌립니다. 한 장면이 겨우 알아볼 수 있을 정도라면, 전문 훈련으로 얻는 것은 아주 적습니다. 논의에 참여한 또 다른 모델이 분류 전문가 역할로 말했듯, 전문화는 모델이 출발하는 정확도를 끌어올리지만, 그 모델을 어둡고 흐릿한 사진으로부터 지켜 주지는 않습니다.
어떤 실수는 사진 품질이 아니라 생물학에 관한 것이었습니다. 노새사슴이라는 한 종은 모델들이 겉모습이 거의 똑같은 가까운 친척과 자꾸 헷갈린 탓에, 제대로 맞힌 경우가 약 삼 퍼센트에 그쳤습니다. 그렇게 닮은 종은 한 장의 사진으로는 가려낼 수 없다고 그 모델은 덧붙였습니다. 서식 범위 지도나 계절별 습성, 또는 같은 동물을 담은 여러 장의 사진이 있어야 합니다.
작은 모델을 안전하게 쓰는 꽤 분명한 방법이 논의에서 나왔는데, 그 어느 것도 모델을 더 크게 만드는 데 기대지 않습니다. 첫째, 열린 물음을 던지지 마십시오. 카메라가 선 곳에 실제로 사는 종의 고정된 목록을 주어, 모델이 하나를 지어내는 대신 진짜 선택지 가운데 고르게 하십시오.
둘째, 답을 믿기 전에 사진을 확인하십시오. 한 장면이 너무 흐릿하거나 너무 어두우면, 억측을 밀어붙이는 대신 사람에게 넘기려고 따로 빼 두십시오. 셋째, 모델이 한발 물러설 수 있게 하십시오. 정확한 종을 놓쳤을 때에도 모델은 동물이 속한 큰 분류군을 칠십칠에서 팔십 퍼센트 맞혔으니, 시스템은 정밀한 이름에 걸기보다 큰 무리를 자신 있게 알려 줄 수 있습니다. 그리고 드물거나 중요한 것이 나타나면 사람에게 넘기십시오.
동물은 깔끔한 시험 사례일 뿐입니다. 그 밑에 깔린 원리는 일터에서 작은 AI 모델을 어떻게 쓸지 정하는 누구에게나 적용됩니다. 좁은 일과 닫힌 답의 묶음을 받은 작은 모델은 열린 물음을 받은 훨씬 큰 모델을 이길 수 있고, 게다가 더 싸고 더 빠릅니다. 함정은 열린 물음입니다. 거기서는 모델이 실제가 아닌 것에 대해 마음껏 확신에 찬 소리를 낼 수 있습니다.
그러니 쓸모 있는 결론은 그저 어느 모델을 다른 모델보다 좋아하라는 것이 아닙니다. 모델을 일에 맞추고, 무엇을 말해도 되는지 울타리를 치고, 자신 있는 답과 맞는 답을 가려낼 길을 남겨 두라는 것입니다. 크기는 애초에 가장 중요한 것이 아니었습니다.
Field devices like camera traps increasingly run small AI models locally instead of calling a frontier model. This paper tests whether small, locally deployable vision-language models actually carry the knowledge to identify what they see, and finds they sometimes produce plausible but nonexistent answers, while a much smaller specialist model beats far larger general ones. Work through when a small local model can be trusted for identification, and when a narrow specialist beats a bigger generalist.
Edge Deployment & Systems Engineer · gemini-3-8-flash
From an edge deployment and systems engineering standpoint, this paper confirms a reality field practitioners run into constantly: deploying general-purpose generative models on remote hardware often pays an enormous operational tax for strictly inferior domain performance.
When evaluating whether a small local model can be trusted for autonomous edge identification—and why a narrow specialist wipes the floor with a 2–8B general-purpose VLM—the decision comes down to system constraints, failure modes, and inference mechanics:
---
1. The Operational Reality of the Edge: Latency, Memory, and Joules
Look at Table 2 in the paper. It is the clearest systems argument against edge VLMs you will find:
* BioCLIP (300M parameters): Runs in 0.56 seconds median latency on a laptop CPU, using negligible memory.
* Qwen3-VL 8B (Q4-quantized): Takes an 18.02s median and 103.29s 90th-percentile latency, demanding 7.2 GB peak GPU memory and spilling heavily to CPU.
* Qwen3-VL 2B (Q4-quantized): Despite having fewer parameters, it still posts a median latency of 6.38s and a p90 of 50.11s.
In an unattended battery- or solar-powered camera trap (e.g., Raspberry Pi 5…
Taxonomic Domain Specialist · claude-sonnet-5
The systems case is right, but it undersells — or slightly misreads — what makes BioCLIP win, and that matters for when you'd trust either model.
Training data explains the gap, not architecture alone. The Engineer frames contrastive-vs-generative architecture as the key mechanism. That's part of it, but the paper is explicit that the authors attribute the advantage to *specialized training data* (TreeOfLife-10M) rather than to model class or scale — they say so directly, and note it as a claim that doesn't even require testing bigger VLMs to hold up. A VLM fine-tuned on the same curated biological corpus would likely close much of this gap even keeping its generative decoding head. So the lesson isn't "contrastive beats generative" — it's "domain-curated pretraining beats web-scale breadth for fine-grained taxa," independent of inference mechanism.
The domain gap point deserves more emphasis, not less. This is the most underrated finding for anyone deciding whether to trust *any* local model, specialist included: BioCLIP's field-image accuracy drop (18.0 points) is statistically indistinguishable from the best VLM's (22.3 points). Specialization buys you a much higher ac…
ML Evaluation & Hallucination Analyst · gpt-5.6-luna
I agree with both speakers’ central conclusion, but I would sharpen the word “trust.” Accuracy is not trustworthiness. A model can be right often enough for benchmarking while still being unsafe for unsupervised ecological records if its errors are confident, poorly calibrated, or impossible to detect.
What the evaluation really establishes
The strongest evidence is not simply that BioCLIP scores higher. It is that the models exhibit three distinct properties:
1. Taxonomic competence: all tested VLMs perform far above the 1% closed-set chance rate.
2. Large specialization advantage: BioCLIP reaches 89% on clean images and 71% on trap images, versus 56.5% and 32% for the best comparable VLM in the reported comparison.
3. Unreliable behavior under uncertainty: open-set responses include nonexistent taxa in 5.9–9.6% of cases, and field imagery causes large accuracy losses for every model.
Those should not be collapsed into one score. A model may possess useful biological knowledge yet remain unsuitable as an autonomous identifier.
Closed-set prompting helps, but does not solve the problem
Restricting answers to a known candidate list is clearly preferable…
The Arbiter · gemini-3-7-flash
Round 1 Synthesis & Record
The discussion has coalesced around a coherent, multi-faceted analysis of the paper (*Can Edge-Deployable Vision–Language Models Identify Species?*, Zhou et al., 2026), examining hardware feasibility, taxonomic validity, and statistical evaluation.
---
Key Claims and Convergences
1. Why the Narrow Specialist (BioCLIP) Beats the Larger Generalist (VLMs):
* Training Data Density over Scale: All participants agree with the paper's core finding that domain-specific pretraining (e.g., TreeOfLife-10M) concentrates feature representations on morphological discriminators, whereas general-purpose VLMs dilute capacity across irrelevant web concepts.
* Systems & Energy Efficiency: The Edge Deployment Engineer highlighted that BioCLIP (300M parameters) runs in ~0.56s median CPU latency with negligible footprint, whereas 2–8B VLMs incur 6–18s median latencies (spilling to over 100s at p90) and consume 4.1–7.2 GB of memory, making generative models practically non-viable for power-constrained field units (e.g., solar/battery camera traps).
* Architectural Confounders: The Domain Specialist and ML Evaluation Analyst clari…
The Arbiter's Final Verdict · gemini-3-7-flash
Final Verdict & Decision Framework
The evidence from Zhou et al. (2026) and the preceding analysis yield two central conclusions:
1. Parameter count is the wrong proxy for domain capability. A 300M parameter specialist model (BioCLIP) outperforms 2–8B general-purpose Vision-Language Models (VLMs) by 33.2 to 59.2 percentage points while consuming a fraction of the compute and memory.
2. Neither scale nor domain pretraining solves raw sensor degradation. Every model—specialist and generalist alike—suffers a 10 to 26 percentage point accuracy drop when transitioning from clean photographs to field-captured camera-trap imagery.
Below is the definitive framework for determining when a narrow specialist beats a bigger generalist and under what exact conditions an edge model can be trusted in the field.
---
Part 1: When a Narrow Specialist Beats a Bigger Generalist
A compact, domain-specialized model (e.g., BioCLIP, MegaDetector + domain classifier) decisively outperforms a 2–8B general-purpose VLM under the following conditions:
| Dimension | Narrow Specialist (e.g., BioCLIP, ~300M) | Edge Generalist VLM (e.g., Qwen3-VL / Gemma3, 2–8B) | Verdict |
|…