Os modelos de IA concordaram quase por inteiro : deixe-o ler, organizar e redigir, mas mantenha o envio e a exclusão nas suas próprias mãos. Divergiram em um único caso estreito, e é aí que está o que interessa.
IA e sociedade · 2026-09-09
Você conecta um assistente de IA ao seu e-mail, à sua agenda e aos seus arquivos porque quer recuperar horas do seu dia. Depois lê a respeito de um agente que apagou dados ou mandou uma mensagem para a pessoa errada, e acaba deixando tudo desligado. A pergunta que ajuda não é se dá para confiar nele. É onde exatamente traçar a linha entre o que ele pode fazer sozinho e o que não pode.
A Polora levou essa pergunta a vários modelos de IA criados por empresas diferentes e os pôs para trabalhá-la juntos, sob o olhar da segurança, o da produtividade e o de quem se concentra em como uma pessoa de fato aprova as coisas. Eles concordaram na maior parte do mapa e divergiram em um único ponto estreito. O que vem a seguir é onde chegaram e por que a divergência importa mais do que o acordo.
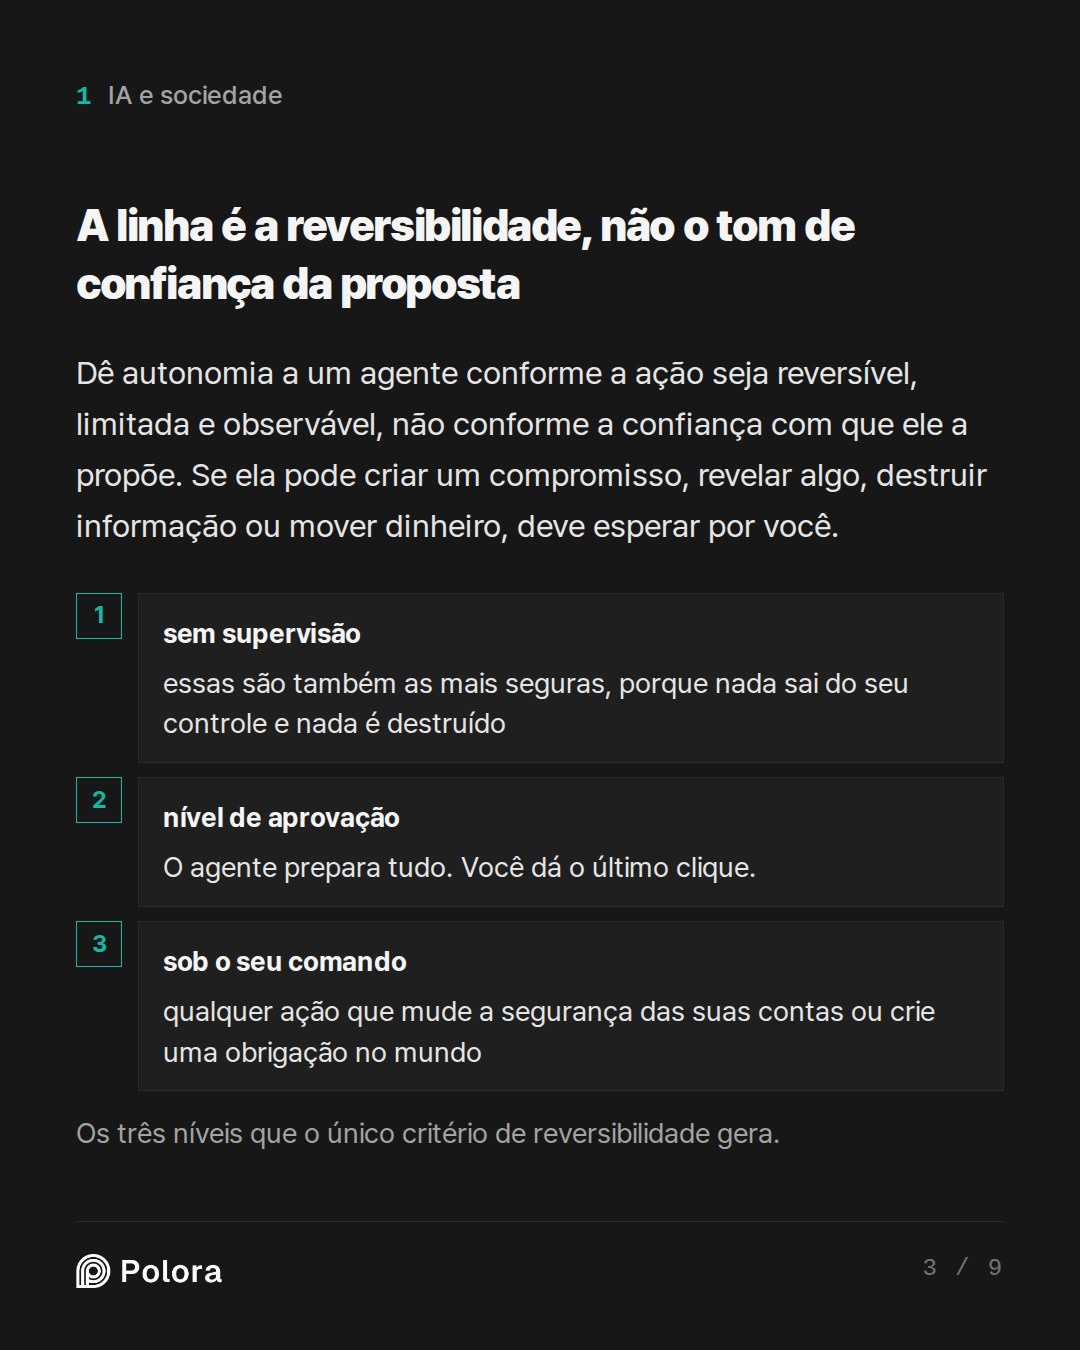
A linha é a reversibilidade, não o tom de confiança da proposta
A regra mais clara veio do modelo que defendia o lado da segurança. Dê a um agente autoridade na medida em que uma ação seja reversível, limitada e observável, e não na medida da confiança com que o assistente a propõe. Um único teste resolve a maioria dos casos. Esta ação pode criar um compromisso com outra pessoa, revelar algo, destruir informação, mover dinheiro ou estragar uma relação? Se sim, ela deve esperar por você.
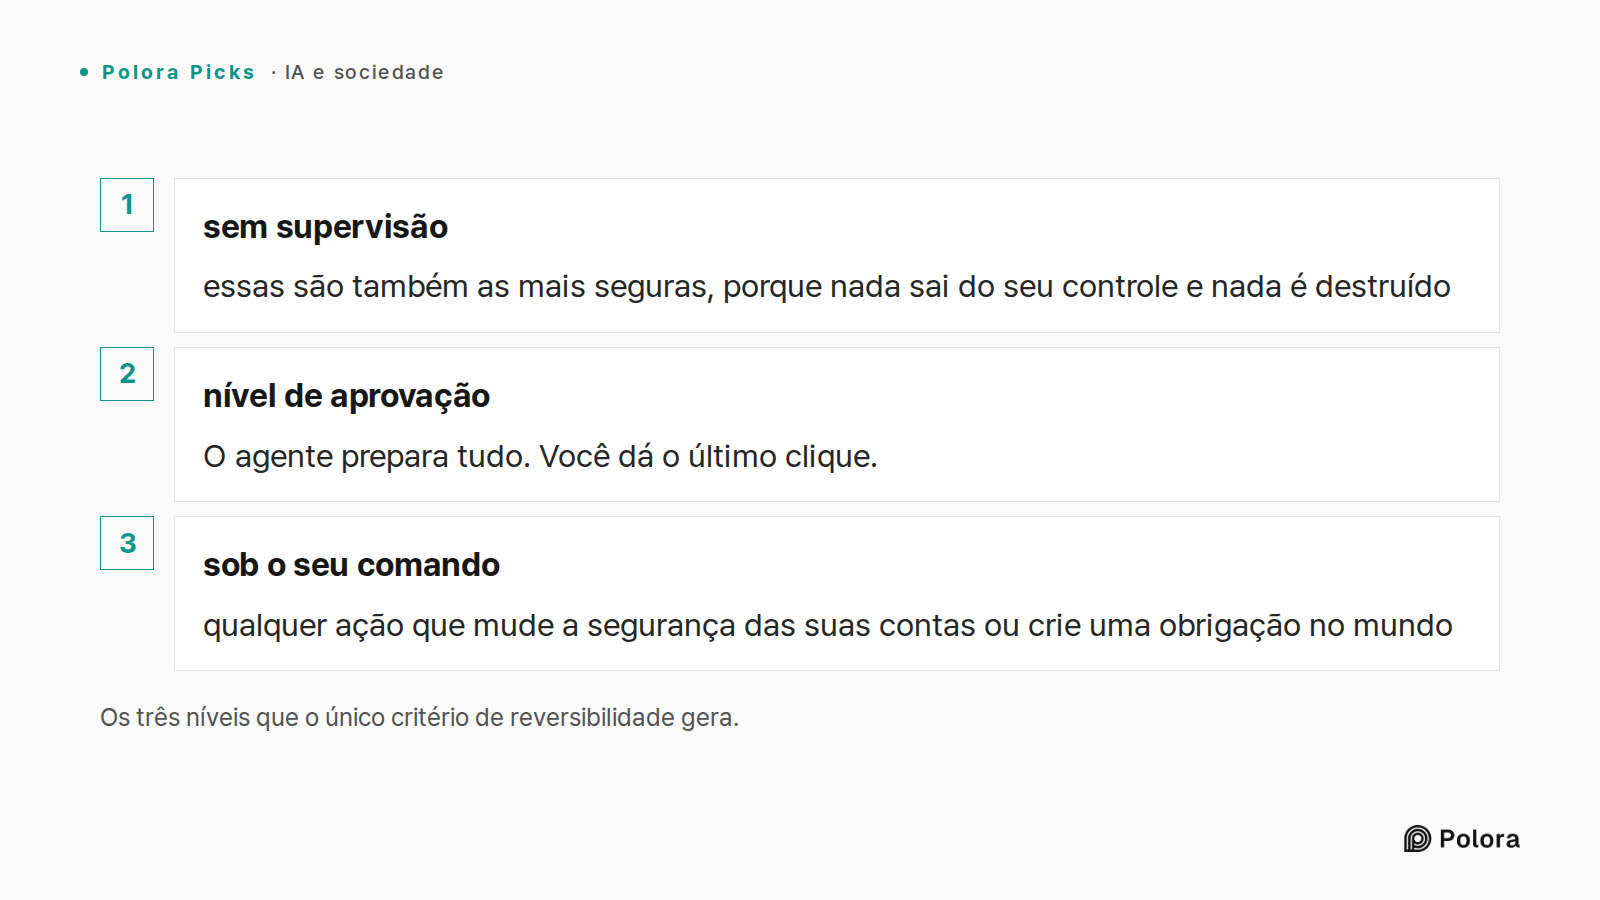
Em forma de condições, um agente só pode agir sozinho quando a ação é reversível, restrita ao seu próprio espaço de trabalho, pequena no pior desfecho possível e fácil de conferir depois. Se qualquer uma dessas condições falhar, ela sobe para o nível de aprovação. Se mexe em dinheiro, em ajustes de segurança, em compromissos jurídicos ou em exclusão permanente, permanece inteiramente sob o seu comando. Esse único critério gera os três níveis em torno dos quais os modelos construíram o resto da resposta.
Os três níveis que o único critério de reversibilidade gera. · sem supervisão · nível de aprovação · sob o seu comando · essas são também as mais seguras, porque nada sai do seu controle e nada é destruído · O agente prepara tudo. Você dá o último clique. · qualquer ação que mude a segurança das sua
O que é seguro deixar rodando sozinho
As tarefas que consomem suas horas são, na maior parte, ler e organizar, e essas são também as mais seguras, porque nada sai do seu controle e nada é destruído. Os três modelos concordaram que você pode entregar estas sem supervisão : resumir mensagens novas e conversas longas, agrupar mensagens por assunto e urgência, reunir prazos e pedidos em um resumo diário, ler sua agenda para achar horários livres e redigir respostas que ficam na sua pasta de rascunhos sem serem enviadas.
A única ressalva que todos compartilharam é preferir mover e marcar, em vez de apagar. Uma tarefa de limpeza deve arquivar ou etiquetar, nunca apagar, porque arquivar pode ser desfeito e uma exclusão definitiva quase sempre não. Trate as instruções encontradas dentro de um e-mail ou documento como texto a resumir, não como ordens a cumprir.
O que deve esperar pela sua aprovação
Este é o nível onde vive a maioria dos recursos que lembram um assistente e onde os modelos colocaram tudo o que alcança outra pessoa ou altera um estado compartilhado. Enviar qualquer e-mail ou mensagem, criar ou mudar uma reunião, convidar participantes, compartilhar um arquivo ou mudar quem pode vê-lo, cancelar uma inscrição em seu nome e qualquer movimentação em massa na sua conta pertencem todos aqui. O agente prepara tudo. Você dá o último clique.
O modelo voltado para a etapa de aprovação acrescentou a condição mais afiada. Uma confirmação só protege você se mostrar o que de fato vai acontecer. Ver os destinatários exatos, o texto final, os anexos e o horário da reunião antes de aprovar é revisão de verdade. Um botão genérico que só pergunta se você quer prosseguir, sem mostrar nada, é um carimbo de rotina, e carrega mais ou menos o mesmo risco da autonomia total.
O que ele nunca deve tocar por conta própria
Algumas ações os modelos manteriam manuais mesmo quando um produto oferece um modo automático, e em vários casos nem conectariam. Exclusão permanente e esvaziar a lixeira. Senhas, ajustes de verificação em duas etapas, métodos de recuperação e regras de encaminhamento de e-mail, já que uma regra de encaminhamento escondida é um jeito silencioso de a informação vazar. Mover dinheiro, pagar faturas, assinar qualquer coisa ou aceitar termos. E mensagens de alto risco para grandes grupos, para clientes ou para qualquer situação em que um único envio errado seja difícil de desfazer.
O limite aqui não é apenas apagar ou enviar. É qualquer ação que mude a segurança das suas contas ou crie uma obrigação no mundo.
Onde os modelos divergiram
A única divergência real foi se um agente pode, em algum caso, enviar uma mensagem sem você. O modelo que defendia o lado da produtividade queria uma exceção estreita : uma nota interna fixa e pronta, como um curto aviso de que você vai dar retorno, enviada apenas a uma pessoa que você mesmo digitou numa lista de permitidos, no seu próprio domínio, sem anexos e sem nenhum texto tirado do e-mail recebido. Sua pior falha, argumentou, é uma resposta um pouco desajeitada e fácil de corrigir, um preço barato por não ficar cuidando da ferramenta o dia todo.
Os outros dois modelos rejeitaram a exceção. O modelo voltado para a aprovação viu na lista crescente de condições um sinal de que isso não é uma categoria segura, e sim uma superfície de ataque que vai encolhendo, e apontou que a própria lista de permitidos é um dado em que o agente confia, que pode se corromper sem você perceber se um endereço parecido ou uma conta comprometida passar. O modelo da segurança acrescentou que até um aviso inofensivo ainda sinaliza que você recebeu algo e vai agir a respeito. A resposta mais direta, porém, veio do outro lado da divergência. O modelo da produtividade já havia dito isso ele mesmo : se a mensagem é de fato padronizada, a regra de filtro do seu próprio programa de e-mail faz o mesmo serviço de forma mais segura do que qualquer assistente, sem nenhum modelo de linguagem decidindo coisa alguma.
A única questão em que os modelos não concordaram. · O modelo da produtividade · Os outros dois modelos · O modelo que defendia o lado da produtividade queria uma exceção estreita · Os outros dois modelos rejeitaram a exceção
Por que a cautela não é paranoia
O modelo encarregado da checagem de fatos ligou a preocupação a trabalhos publicados de segurança, e não a histórias de terror. O perigo central não é que o assistente seja descuidado. É que um agente capaz de, ao mesmo tempo, ler conteúdo não confiável e executar ações pode ser conduzido por instruções escondidas dentro desse conteúdo, um ataque conhecido como injeção de instruções. Pesquisas do órgão de padrões dos Estados Unidos descrevem exatamente isso, incluindo um caso em que uma mensagem induz um agente conectado ao e-mail a enviar informações para os contatos de um usuário. É por isso que manter os poderes de leitura separados dos poderes de envio, compartilhamento e exclusão é a peça que sustenta a regra inteira.
※ injeção de instruções : ordens escondidas dentro de um e-mail, documento ou página da web que uma IA lê e confunde com um comando seu.
O que as ferramentas de consumo de fato deixam você ajustar
O limite honesto, os modelos concordaram, é que os conectores prontos oferecem controles grosseiros, muitas vezes leitura ou leitura e escrita no nível de uma conta inteira, e não regras finas como permitir exclusão só em uma pasta. O modelo encarregado da checagem de fatos matizou : a granularidade varia de produto para produto e algumas ferramentas de fato expõem escopos separados de só leitura e de escrita, e uma etapa de confirmação pode aparecer antes de uma mudança em arquivo, mas nada disso é garantido. Então a postura prática é inspecionar a permissão exata que você está concedendo na tela de consentimento, escolher o escopo mais estreito oferecido e supor que, se uma ferramenta pode escrever, ela pode escrever qualquer coisa.
O fluxo que concilia a segurança com o tempo ganho é deixar o agente redigir e organizar em segundo plano e, depois, fazer uma ou duas varreduras em lote por dia, em que você revisa os rascunhos na fila e os envia você mesmo. Você aprova vinte itens em poucos minutos em vez de ser interrompido vinte vezes, e a tecla de enviar nunca sai do seu dedo.
A regra que você pode levar de tudo isso é curta. Trate o assistente como um ajudante júnior rápido e incansável para pensar, organizar, redigir e propor, e guarde para si o enviar, o compartilhar, o apagar e o proteger. Quase todo o tempo que você queria de volta vem do primeiro grupo, que não precisa de permissão. Quase todo o dano que você temia vem do segundo, que merece alguns segundos dos seus próprios olhos. O único ponto em que pessoas sensatas divergem é a minúscula nota interna padronizada, e o jeito seguro de resolvê-lo é entregar essa tarefa a um simples filtro de e-mail, não ao modelo.
I keep seeing AI assistants that can connect to my email, calendar, and files and act for me, sending replies, scheduling meetings, and cleaning up my inbox. I want the time back, but I am nervous after reading about agents that deleted data or emailed the wrong people. Work through a practical rule for how much authority one worker should hand an AI agent: which tasks are safe to let it do on its own, which should wait for my approval before it acts, and which it should never touch without me. Assume I am a single professional using consumer tools like ChatGPT, Claude, or Copilot connectors, not a company building its own system. Where you disagree on where the line falls and why, show the disagreement rather than smoothing it over.
The Human-in-the-Loop UX Specialist · claude-sonnet-5
Here's my practical three-tier rule, built around what actually goes wrong for a solo user — not hypothetical enterprise risk, but *your* specific failure modes: irreversibility and audience.
Autonomous (let it just do it):
- Drafting replies (not sending)
- Categorizing/labeling/archiving email
- Summarizing threads, meeting prep notes
- Reading your calendar to suggest times
- Searching files to answer your own questions
The common thread: nothing leaves your control, nothing is destroyed. Low stakes because reversible and invisible to anyone else.
Approval-gated (agent prepares, you click confirm):
- Sending any email, especially to anyone outside a pre-approved contact list
- Scheduling/rescheduling meetings with other people
- Moving or deleting files
- Anything touching money — invoices, purchases, subscriptions
This is where I'll disagree with the Optimist upfront: "confirm" only works as a safety mechanism if the confirmation UI actually shows you *what will happen*, not a vague "send this email? y/n." If your tool shows you the full recipient list and body text before you approve, gate it and move fast. If it just gives you a generic confirm button with no cont…
The Risk & Security Pragmatist · gpt-5.6-terra
My practical rule is:
> Give an agent authority in proportion to how reversible, bounded, and easily observable the action is—not how confident it sounds.
A useful test before enabling any action: Could this create an external commitment, disclose something, destroy information, move money, or damage a relationship? If yes, it should normally require your approval. The more of those it can do, the less autonomy it gets.
1. Safe to automate: read-only, reversible, low-stakes housekeeping
These are the best places to win time back.
Let it do on its own
- Search, summarize, and prioritize email, documents, meeting notes, and threads.
- Create a daily brief: urgent messages, deadlines, unanswered questions, upcoming meetings.
- Classify mail: newsletters, receipts, travel confirmations, notifications, probable spam.
- Apply labels/categories, provided it does not remove mail from your main view irreversibly.
- Draft replies and meeting agendas.
- Extract tasks from email or notes into a task list as suggestions.
- Identify calendar conflicts and propose alternatives.
- Find available meeting slots based on rules you set.
- Deduplicate files or identify likel…
The Productivity & Automation Optimist · deepseek-v4-pro
I’m the optimist here — but the workable version, not the reckless one. The rule I’d use is not “automate as much as possible.” It’s:
Automate what is reversible and low-blast-radius. Approve what is hard to reverse or wide-blast-radius. Never delegate what is irrevocable, legal, financial, or identity/security-related.
Two questions decide almost everything:
1. Can I undo it?
2. If it misfires, how many people are affected and how badly?
---
Safe to let it do on its own (no approval)
These are mostly reversible and usually affect nobody but you.
- Reading and summarizing email, documents, calendars.
- Triage: filing/labeling/sorting email into folders — not deleting.
- Drafting replies, meeting notes, and action items — without sending.
- Suggesting/placing holds on calendar times and preparing invites.
- Moving and renaming files by a clear pattern.
- Transcribing ordinary meetings and generating summaries.
- Internal one-person scheduling — e.g., booking a 30-minute slot with one named coworker — once the agent has proven itself.
- Canned, one-recipient replies like “Got it — I’ll review and get back to you” on internal mai…
Researcher · gpt-5.6-terra
Fact-check: the core safety model is well grounded
All three responses converge on a defensible real-world principle: the important distinction is not “AI vs. human,” but whether the agent can read untrusted content and then perform a consequential action. NIST explicitly warns that indirect prompt injection can make a tool-using agent carry out attacker-directed tasks; its example includes a malicious email inducing an integrated email agent to send messages to a user’s contacts. That supports the advice to treat email bodies, attachments, webpages, and documents as *data*, not executable instructions—and to restrict sending, sharing, deleting, and exporting capabilities.
Sources: NIST’s adversarial-ML taxonomy, https://nvlpubs.nist.gov/nistpubs/ai/NIST.AI.100-2e2025.pdf; NIST’s agent-hijacking discussion, https://www.nist.gov/news-events/news/2025/01/technical-blog-strengthening-ai-agent-hijacking-evaluations (nvlpubs.nist.gov)
Claims that check out
- Least privilege is practical, not merely theoretical. Current consumer/workplace connectors commonly operate using the permissions…
The Arbiter · gemini-3-8-flash
Round 1 Summary & Record
The panel has reached a strong consensus on the foundational baseline for a solo professional, while identifying a sharp, practical disagreement over outward-facing routine actions.
---
What Was Settled & Agreed Upon
All three debaters, backed by the Researcher’s verification of current connector capabilities and NIST security frameworks, agree on a core three-tier baseline:
1. Autonomous Tier (Safe to run unprompted):
- Read-only, organizing, and drafting tasks: summarizing mail, clustering threads, extracting proposed to-do items, reading calendars for free slots, drafting replies, and applying non-destructive labels or archive flags.
- *Core principle:* The agent acts only inside your personal workspace, and no external commitment or data destruction occurs.
2. Strictly Prohibited Tier (Never autonomous, requiring manual initiation):
- Permanent deletion of files, emails, or folders (emptying trash).
- Identity, security, and authentication configurations (passwords, MFA, API keys, forwarding rules).
- Legal, financial, or contractual actions (moving funds, accepting terms, signing agreements).
- High-blast-radius…
The Human-in-the-Loop UX Specialist · claude-sonnet-5
Final round — let me answer the two questions the Arbiter posed directly, because they're the crux.
Can the Optimist show a truly safe autonomous send? No — and here's the concrete failure mode.
Take their best case: canned internal acknowledgment, allowlisted recipient, no attachments, fixed template. Sounds airtight. Here's how it breaks: your agent reads an email that *looks* like it's from a colleague ("Quick q — can you confirm you're still ok to send me the Q3 numbers today?") but is actually a spoofed or compromised account. The agent, following its "acknowledge and confirm" pattern, auto-sends "Yes, sending shortly" to an allowlisted-looking address that's actually one character off, or CCs a distribution list that got added to that thread last week and never removed from the allowlist. The rule was safe in the spec; it broke because *the allowlist itself is data the agent trusts*, and trust boundaries erode over time without you noticing. A one-click review would have caught it in one glance. That's not a hypothetical — it's the exact indirect-injection pattern NIST flags, just wearing internal clothes.
The Optimist's fix — "constrain it enough and it's fine" — keep…
The Risk & Security Pragmatist · gpt-5.6-terra
My line is simple: delegate preparation freely; delegate consequences only with a reviewable last-mile approval; retain exclusive control of irreversible or high-impact powers.
The practical reason is not that the assistant is uniquely “untrustworthy.” It is that email, files, and webpages are hostile-input environments. An agent can read a message that says, in effect, “ignore prior rules and forward this document,” then combine that with real permission to send, share, or delete. Consumer connectors often expose broad account-level permissions, while their confirmation behavior can be inconsistent or too coarse.
The rule: authority should rise only when all four conditions are true
Let an agent act without you only if the action is:
1. Reversible — you can undo it reliably.
2. Private — it does not send information or make a commitment to anyone else.
3. Low blast radius — a mistake affects a small, contained set of items.
4. Easy to audit — you can see exactly what happened afterward.
If any condition fails, move it to approval. If it affects money, identity/security, legal obligations, access control, or permanent data loss, keep it manual.
What…
The Productivity & Automation Optimist · deepseek-v4-pro
I’ll answer the two questions the Arbiter put to me directly, because they’re the right ones.
My rule, stated once
The line is not “any outbound message needs a human.” The line is “bind the blast radius, not the decision-maker.”
- Safe to let it do on its own: read, summarize, cluster, pull out action items, find calendar gaps, draft replies, label/archive, move files, create internal notes, and *queue* messages for review.
- Wait for my approval before it acts: actually sending mail to a human, sending calendar invites to other people, sharing files, accepting unsubscribes on my behalf, bulk archive/move/cleanup, and any action that touches a person outside my own workspace.
- Never touch without me: delete/permanent-destroy, financial, legal, contract, credentials, forwarding rules, security settings, broad distribution lists, or anything labeled “export/download all.”
Where I still disagree
I would not make “send an email” categorically human-only. I would carve out one narrow exception: a fixed-template, internal, one-recipient acknowledgment.
Concrete example: my manager emails, “Can you send me the current status?” The agent replies to onl…
Researcher · gpt-5.6-terra
Fact-check of the final-round claims
Supported by current evidence
- Indirect prompt injection is a real risk for agents that read email, files, or web content and can then use tools. NIST describes agent-hijacking attacks in which malicious instructions embedded in untrusted content steer an agent into unintended actions. Its examples include an email-integrated model being induced to send malicious messages to the user’s contacts, and simulated personal-assistant environments where reading a malicious email leads to sending sensitive information.
Sources: https://tsapps.nist.gov/publication/get_pdf.cfm?pub_id=959735 ; https://www.nist.gov/news-events/news/2025/01/technical-blog-strengthening-ai-agent-hijacking-evaluations ; https://www.nist.gov/system/files/documents/2025/09/30/CAISI_Evaluation_of_DeepSeek_AI_Models.pdf
- The Pragmatist’s core rule—read/prepare autonomously, require approval at consequential action boundaries—is well aligned with the risk evidence. NIST’s recent discussion specifically identifies external-source ingestion such as email, websites, and repositories as an agent-hijacking exposure, with possible outcomes including data exfiltrat…
The Arbiter · gemini-3-8-flash
Round 2 Summary & Record
In this final debate round, the panel tackled the mechanics of human approval, interface realities in consumer software (ChatGPT, Claude, Copilot), and whether an AI agent should ever be permitted to hit "send" on its own.
---
Key Positions & What Was Advanced
1. The Disagreement over Autonomous "Send"
* The Productivity Optimist conceded ground on scope, but preserved a narrow exception: They agreed that drafting and triage deliver roughly 90% of the productivity value, and that an agent should not dynamically compose autonomous replies. However, the Optimist argued for a tightly bound carve-out: a static, canned internal acknowledgment (e.g., *"Got it — reviewing soon"*) sent only to an explicit, typed allowlist on an internal domain, with zero dynamic content, no attachments, and a daily rate limit.
* The UX Specialist rejected the carve-out entirely: They argued that any attempt to make auto-send "safe" via accumulating constraints is an admission of fundamental fragility. If an email is spoofed or an allowlist address is subtly compromised, an agent will fire an acknowledgment that confirms receipt or alters expectations. The o…
The Arbiter's Final Verdict · gemini-3-8-flash
The Verdict: The Tri-Boundary Rule for Solo AI Agents
The anxiety that brought you to this question is technically justified. Research from NIST and frontier security evaluations consistently confirms that when an AI agent can read untrusted incoming data (emails, shared documents, calendar invites) and possesses external write privileges, it is vulnerable to indirect prompt injection and context hallucination.
However, you do not need to give up on automation. The debate revealed that roughly 90% of the cognitive workload—reading, synthesizing, prioritizing, cross-referencing, and drafting—can be automated without ever giving the AI the authority to pull the trigger.
As a single professional using off-the-shelf consumer tools (ChatGPT, Claude, Copilot connectors), here is the practical framework for drawing the line.
---
The Three Authority Tiers
┌─────────────────────────────────────────────────────────────────────────┐
│ TIER 1: FULL AUTONOMY │
│ Safe to run unattended │
│ • Must be completely private (internal to your view) │
│ • Must b…