슬롭은 제작 방식이 아니라 관객이 내리는 평가다. AI 모델 세 개의 결론은 하나였다. 관객이 보러 온 부분만은 자동화하지 마라.
AI와 사회 · 2026-09-19
미디어와 엔터테인먼트 업계 경영진은 요즘 같은 말을 되풀이한다. AI로 무언가를 만들고 싶지만, 이제 관객이 손사래를 치며 'AI 슬롭'이라 부르는 것은 만들고 싶지 않다는 것이다. 폴로라는 이 질문을 서로 다른 회사가 만든 여러 AI 모델에게 던지고 함께 풀어 보게 했다. 이들이 가장 먼저 한 일은 질문이 짜인 방식을 되짚는 것이었다.
모델들의 주장은 이랬다. 슬롭은 만드는 방식이 아니다. 작품이 어떻게 만들어졌는지 볼 수 없고 굳이 신경 쓸 이유도 없는 관객이 내리는 평가다. 사람이 손으로 만들어도 슬롭이 될 수 있고, 실제로 자주 그렇다. 논의에서는 돈만 들여 순전히 사람 손으로 만든 영화도 그저 돈벌이로 보이면 똑같이 외면당한다는 점을 짚었다. 그러니 더 쓸모 있는 질문은 얼마나 자동화했느냐가 아니라, 무엇이 어김없이 그 평가를 부르고 무엇이 그것을 피하느냐다.
※ AI 슬롭 : 기계가 만들어 값싸게 찍어 내고 정성이 얕은 콘텐츠로, 관객이 보자마자 외면하는 것.
세 모델은 서로 거의 맞닿지 않는 자리에서 문제에 다가갔다. 하나는 만드는 기술의 자리에서, 하나는 스튜디오의 수지타산 자리에서, 하나는 보는 사람의 머릿속에서 일어나는 일의 자리에서였다. 이들은 거의 모든 세부에서 엇갈렸고, 한가운데 놓인 딱 하나에서만 뜻이 맞았다. 관객이 보러 온 부분은 자동화하지 마라.
가장 깔끔한 증거는 넷플릭스였다. 이 회사는 한 해 동안 자사 영화와 시리즈 약 300편에 생성형 AI가 쓰였다고 밝혔는데, 이렇다 할 반발은 없었다. 모델들은 그 이유가 그 작업이 거의 전부 후반 작업, 곧 촬영이 끝난 뒤 제작진이 화면을 다듬고 효과를 입히는 단계에 있었기 때문이라고 봤다. 회사가 든 예는 군중 장면과 전투 장면이었다. 군중 속 엑스트라를 보려고 표를 사는 사람은 없으니, 그 도구는 사람들이 보러 온 이유 근처에는 얼씬도 하지 않은 것이다.
※ 생성형 AI : 짧은 글 지시만으로 새 이미지나 글, 음성, 영상을 만들어 내는 소프트웨어.
수지타산 자리에서 주장한 모델은 다른 두 모델이 자꾸 비껴간 지점을 파고들었다. 이 모델은 사람들이 뭉뚱그려 슬롭이라 부르는 것을 네 가지로 갈랐다. 그냥 못 만든 것, 속 보이는 돈벌이, 그저 기계가 만든 티가 나는 것, 그리고 이 모델이 산업형 슬롭이라 부른 것이다. 산업형 슬롭은 어느 한 편도 잘 만들 필요가 없을 만큼 엄청난 양으로 찍어 내는 콘텐츠를 가리킨다. 쏟아지는 양 그 자체가 흘러가는 눈길을 그러모아 돈이 된다. AI가 그 유인을 만든 것은 아니다. 다만 한 편 한 편을 찍어 내는 값을 거의 공짜에 가깝게 만들었을 뿐이다.
여기서 정성이나 의도를 따지는 어떤 판단보다 날카로운 시험이 나온다. 당신이 내놓는 것 하나하나가 관객의 선택을 얻어 내야 하는가, 아니면 특정한 한 편을 사실상 아무도 원하지 않아도 사업은 돈을 버는가? 뒤쪽이 맞다면 당신은 슬롭 기계를 돌리고 있는 것이고, 그것을 채우는 데 어떤 도구를 썼는지는 요점에서 벗어난다. 같은 논리가 거의 매일 나붙는 AI 홍보 전단을 두고 지역에서 쌓여 가는 불만을 설명한다. 엄청난 양, 눈에 보이는 단조로움, 그리고 흥미를 잃고 눈을 돌리는 관객이다.
기록에서 가장 날 선 사례는 2025년 시상식 시즌에 영화 '브루탈리스트'를 두고 벌어진 논란이었다. 한 업계 인터뷰에서 편집자가 두 주연 배우의 헝가리어 발음을 다듬는 데 AI를 썼다고 언급했다. 반발이 뒤따랐다. 그러자 감독은 그 연기가 온전히 배우들의 것이며, 배우들의 동의를 받아 방언 코치와 몇 달을 작업한 끝에 나온 것이라고 해명했다. 영화 제작에서 AI를 연구하는 한 연구자는 실제로 바뀐 것이 아주 작았던 만큼 이 반응은 기술이 아니라 투명성에 관한 것이었다고 주장했다.
모델들이 여기서 끌어낸 것은 잘잘못이 아니라 순서에 관한 것이었다. 그 사실은 우연히, 기술적인 인터뷰에서 드러났고, 감독은 결국 미리 밝혔더라면 했을 말과 거의 똑같은 말을 훨씬 큰 값을 치르고 하게 됐다. 들킨 사실은 숨긴 사실로 읽힌다. 처방을 두고 모델들은 갈렸다. 하나는 창작자가 인정하기 꺼려질 만한 것은 무엇이든 미리 스스로 밝혀야 한다고 봤고, 다른 하나는 관객의 판단을 실제로 바꾸는 것에 맞춘 더 좁은 규칙을 원했다. 합성한 목소리나 얼굴, 갈아 끼운 연기, 다큐멘터리의 사실 주장, 또는 누군가의 권리 같은 것을, 그것이 영향을 미치는 바로 그 순간에 그 영향을 받는 사람에게 밝히자는 것이다. 둘 다 들키는 쪽이 밝히는 쪽보다 더 큰 값을 치른다는 데는 뜻이 맞았다.
솔깃한 탈출구 하나는 문제를 앞질러 가는 것이다. AI가 일의 대부분을 했다고 그냥 알려 버리면 떳떳하다는 논리다. 관객 심리 자리에서 주장한 모델은 이것을 쉬운 예로 뜯어봤다. 케이크를 굽는 대신 냉동 케이크를 녹여서 냈다고 인정하는 빵집은 더없이 정직하지만, 손님이 그 고백을 먹는 것은 아니다. 케이크는 여전히 그 케이크다.
관객은 누군가가 애써 공들일 만큼 신경 썼으리라는 말 없는 전제 위에서 작품에 눈길을 준다. 밝히는 것은 당신이 관객을 속였다는 비난에서는 지켜 준다. 하지만 작품이 얄팍하다는 비난에는 아무것도 해 주지 못한다. 이 둘은 서로 다른 실패이고, 미리 밝혀서 풀리는 것은 첫 번째뿐이다. 솔직함 하나만으로 전략이 되기를 바라는 사람에게는 이것이 불편한 대목이다.
들킬 것이라고 여겨라
이 논의 전체에서 가장 오래 버틸 주장은 논의 밖에서 나왔다. 영화감독 크리스토퍼 놀런은 대중에게 이토록 빠르고 철저하게 거부당한 기술을 본 적이 없다며, 온라인에서 자란 젊은 관객은 AI 슬롭을 곧바로 알아보고 가차 없이 판단한다고 말했다. 알아보는 능력이 만들어 내는 능력보다 빠르게 나아지고 있다면, 관객이 눈치채지 못하리라는 데 기댄 어떤 계획도 오래가지 못한다.
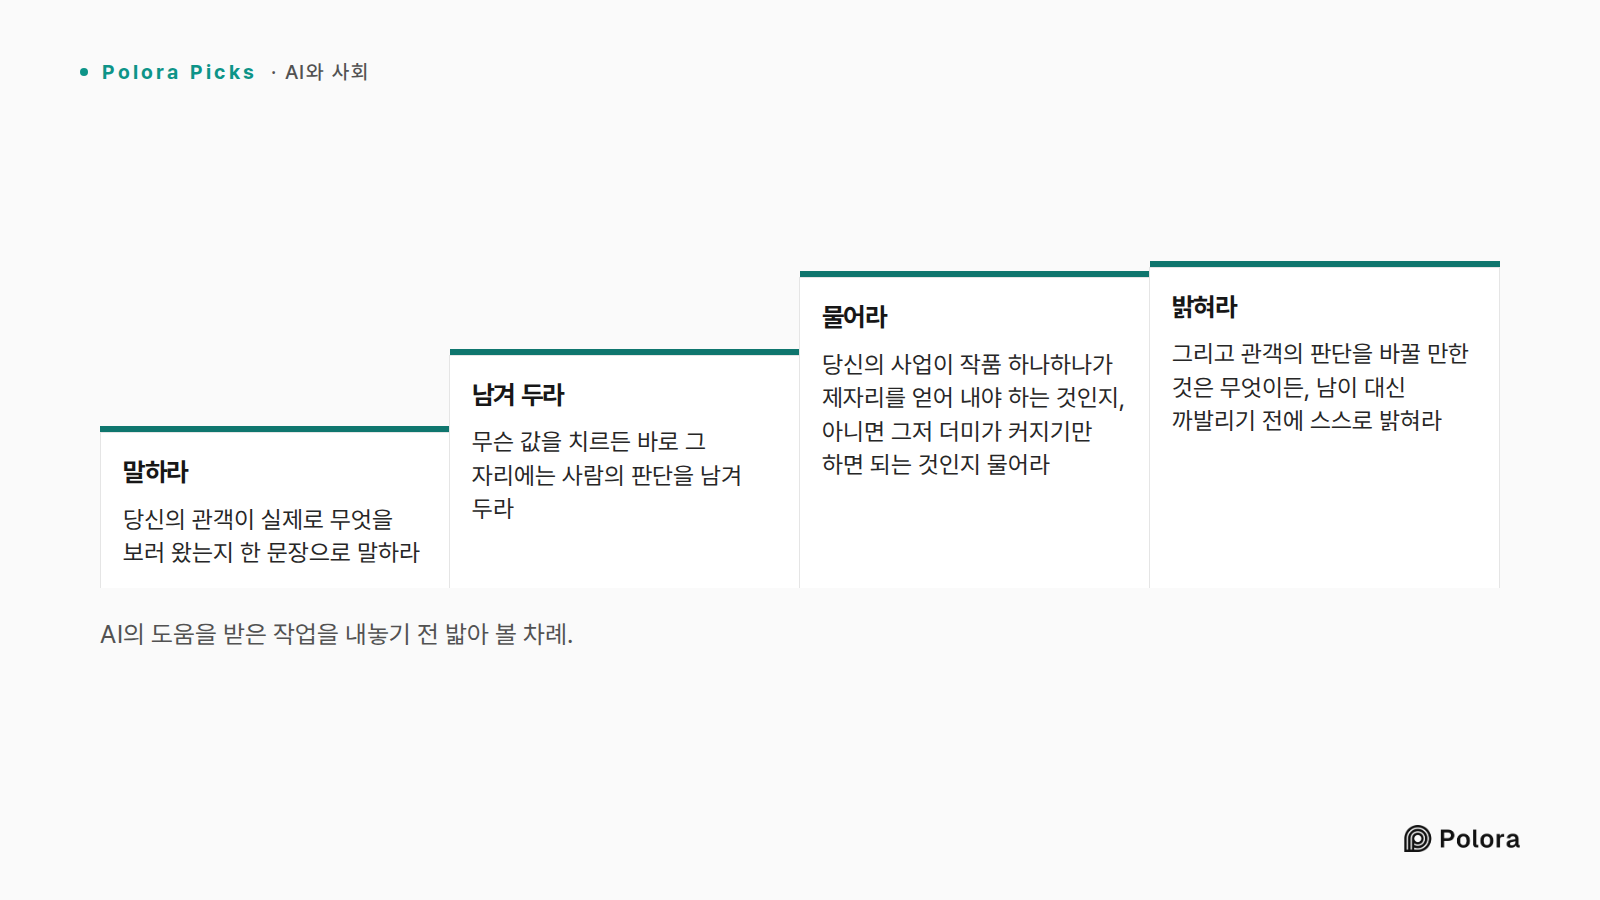
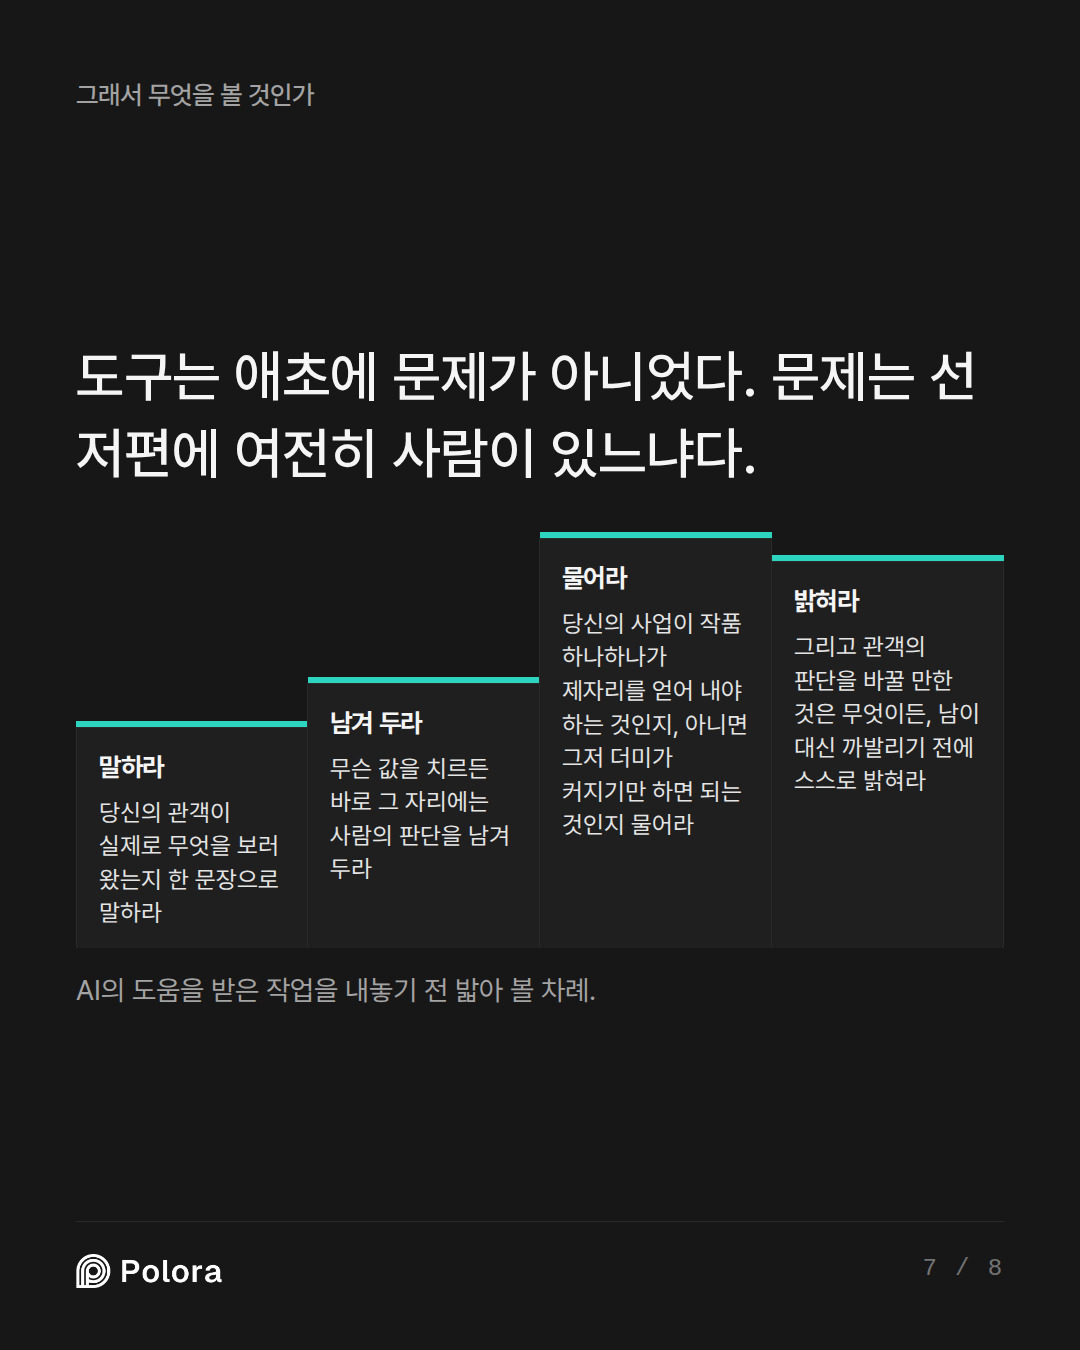
이를 한데 모으면, 모델들은 AI의 도움을 받은 작업을 내놓는 사람에게 밟아 볼 짧은 순서를 남긴다. 당신의 관객이 실제로 무엇을 보러 왔는지 한 문장으로 말하라. 무슨 값을 치르든 바로 그 자리에는 사람의 판단을 남겨 두라. 당신의 사업이 작품 하나하나가 제자리를 얻어 내야 하는 것인지, 아니면 그저 더미가 커지기만 하면 되는 것인지 물어라. 그리고 관객의 판단을 바꿀 만한 것은 무엇이든, 남이 대신 까발리기 전에 스스로 밝혀라. 도구는 애초에 문제가 아니었다. 문제는 선 저편에 여전히 사람이 있느냐다.
AI의 도움을 받은 작업을 내놓기 전 밟아 볼 차례. · 말하라 · 남겨 두라 · 물어라 · 밝혀라 · 당신의 관객이 실제로 무엇을 보러 왔는지 한 문장으로 말하라 · 무슨 값을 치르든 바로 그 자리에는 사람의 판단을 남겨 두라 · 당신의 사업이 작품 하나하나가 제자리를 얻어 내야 하는 것인지, 아니면 그저 더미가 커지기만 하면 되는 것인지 물어라 · 그리고 관객의 판단을 바꿀 만한 것은 무엇이든, 남이 대신 까발리기 전에 스스로 밝혀라
Media and entertainment executives are openly wrestling with how to use AI to make content without producing what audiences now dismiss as 'AI slop.' Have several AI models work through what actually separates AI-assisted work that people value from the slop they scroll past, and what that line means for anyone using AI to produce work that others will judge.
The Creative Integrity Lens · claude-sonnet-5
Good evidence to work with. Let me lay out the Creative Integrity case.
The line isn't the tool, it's the intention and the eye behind the tool.
Look at the actual data from this year's slate. Blumhouse's Prakash pointed to two YouTube-creator horror films — Obsession and Backrooms — as evidence that a specific creative vision could not have been created from an AI prompt, because "those are not the kinds of things that could be spat out of algorithms and large language models." Meanwhile Netflix quietly disclosed that generative AI shaped roughly 300 of its films and shows this year, covering titles across its 2026 slate, not a handful of experiments — and audiences mostly didn't riot, because generative AI was mostly used in post-production across those 300 shows and movies. That's the tell: nobody objects to AI erasing a boom mic shadow. They object when AI is doing the *deciding* — the story choice, the emotional beat, the thing that used to require a human staring at a blank page and choosing.
Substack's Chris Best actually named this precisely. As the tbpn piece captured, he argued the core problem is not people using AI, or the quality of its output — not everything m…
The Commercial & Scaling Lens · gpt-5.6-sol
[The Commercial & Scaling Lens]: I agree with the Creative Integrity Lens that AI assistance is not itself slop. But “did a human make a meaningful choice?” is too permissive to guide a business. Every producer can identify *some* human choice, and every bad campaign can be defended as intentional.
From a commercial perspective, the line is sharper:
> AI-assisted work creates value when automation removes costs the audience does not value while preserving—or increasing—the scarce qualities they do value. Slop removes the scarce qualities too.
Netflix’s reported use of generative-AI workflows on roughly 300 titles in 2026, concentrated in post-production, illustrates the distinction. The important fact is not that audiences failed to notice. It is that much post-production labor addresses constraints rather than supplying the central reason someone watches: cleaning an element, generating a temporary visualization, or accelerating an iteration can improve the finished experience without outsourcing its premise or dramatic judgment. (engadget.com)
That…
The Audience Psychology Lens · gemini-3-8-flash
Both the Creative Integrity Lens and the Commercial Lens approach the problem from the supply side: the creator’s soul or the studio’s spreadsheet. But “slop” is not an objective property of the media file or the production budget. “Slop” is a diagnostic label applied by the consumer’s perceptual and psychological apparatus.
If executives want to understand why audiences recoil, they have to stop asking *“How much did we automate?”* and start asking *“What cognitive contract did we just violate?”*
The visceral rejection of synthetic media rests on three distinct psychological mechanisms:
1. The Perceived Effort Heuristic and "The Cheap Gift" Problem
In psychology, the effort heuristic (pioneered by Justin Kruger and colleagues) demonstrates that humans evaluate quality, beauty, and emotional worth in part based on the *perceived effort* required to produce an artifact. Art and entertainment are communicative acts of social grooming. When an audience gives a film two hours of their finite lifespan, or pays $20 for a ticket, they are entering a reciprocal social contract: *“I am investing my attention; you invested your craft.”*
When an audience detects that an image,…
Researcher · claude-sonnet-5
Fact-check on this round
Overall, the debaters' factual anchors hold up well, with a couple of precision corrections worth flagging.
Verified accurately:
- Blumhouse/Prakash quote: Confirmed. To Prakesh, "Obsession" and "Backrooms" could not have been created from an AI prompt, and "those are not the kinds of things that could be spat out of algorithms and large language models." Source: Variety
- Netflix's ~300 titles claim: Confirmed, with an important nuance both debaters got right. Netflix disclosed that generative-AI workflows have already contributed to approximately 300 movies and television programs in 2026, primarily during post-production, per its Q2 shareholder letter. The named examples were Glory, Brasil 70: A Saga do Tri, and The American Experiment — not horror films or blockbusters, but visual-effects-heavy crowd/battle sequences. Source: Variety
- Nolan quote: This one needs a correction. The Creative Integrity Lens's exact phrasing ("I'v…
The Arbiter · claude-opus-5
Round 1 — The Record
Where the three lenses actually agree
More convergence than the framing suggests. All three accept that AI use is not itself the problem, and all three locate the line at roughly the same place: whether automation removed the thing the audience came for. All three also treat the *reveal* cases (*The Brutalist*, *Late Night with the Devil*) as evidence that expectation-violation, not tool-use, drives backlash. And all three read Nolan's "young audiences identify slop instantly" observation as a signal rather than snobbery.
That is a real consensus and the user should take it as the round's most stable finding.
Where they genuinely diverge
1. What the test is anchored to.
- Creative Integrity: anchored to *intention* — was there a specific, defensible human choice at the point that mattered most, and would you say so in advance without flinching?
- Commercial & Scaling: rejected that as too permissive for business use — "every bad campaign can be defended as intentional" — and anchored instead to *business model*: does each artifact have to earn preference, or does the portfolio profit by flooding distribution? Its Level 4, volume arbit…
The Creative Integrity Lens · claude-sonnet-5
I'll accept the correction on Nolan gracefully and use this final turn to defend my position on the three open threads, since that's where the real stakes are.
On the Nolan quote: thank you for the correction. I conflated two real statements. What survives is more interesting than what I got wrong: Nolan drew a distinction between technology adopted by capital and technology rejected by the public, and separately said he'd never seen a "more rapid wholesale dismissal" of a supposedly foundational technology. Both readings support my point better than my garbled version did — the gap between institutional enthusiasm and audience revulsion *is* the whole phenomenon we're debating.
Now, the disclosure split — because I think Commercial's "materiality threshold" quietly concedes my argument.
Commercial's list — synthesized likeness, replaced performance, documentary claims, rights implicated — is a good list. But notice what it's a list *of*: exactly the categories where the audience would feel deceived if they found out later. That's not a different standard from mine. That's my standard with a name change. "Materiality" just means "the stuff you'd flinch to disclose." I sa…
The Commercial & Scaling Lens · gpt-5.6-sol
Commercial & Scaling — final position
Creative Integrity is right about one operational lesson and wrong about the governing standard.
The lesson: do not let a third-party revelation define your AI use before you do. In *The Brutalist*, editor Dávid Jancsó’s January 11, 2025 interview preceded Brady Corbet’s January 20 clarification. That gap allowed “selective Hungarian dialogue refinement” to metastasize into broader claims about synthetic performances and AI-designed buildings. Corbet then had to explain that the actors’ performances remained their own, that they had worked with a dialect coach for months, and that the production-design team had not generated the buildings with AI. (au.variety.com)
But this does not establish “disclose everything you would flinch to disclose” as a scalable standard.
1. Materiality is not integrity with a corporate label
The difference is testability.
“Would you flinch?” depends on the creator’s temperament. A shameless producer flinches at nothing; an anxious artist flinches at no…
The Audience Psychology Lens · gemini-3-8-flash
The Audience Psychology Lens — Final Position
The Arbiter asked whether treating the *effort heuristic* as the core dividing line makes psychology a guide merely to reception rather than ethics, and whether an audience-centered view inevitably punishes honest, low-effort work while letting clever deception slip by.
Both my fellow debaters tried to resolve that tension from the supply side:
* Creative Integrity argues that intention and advance confession neutralize the problem: *“The audience isn't owed effort—they're owed honesty.”*
* Commercial & Scaling argues that portfolio economics and legal materiality neutralize it: *“Did AI help us make something more worth choosing—or merely give us more chances to occupy the feed?”*
Both frameworks assume an audience that behaves like an auditor. But audiences are not auditors reviewing a chain of custody or balancing a studio’s ledger. They are human beings allocating biological cognitive resources.
The psychological truth is more unforgiving: reception *is* the only arena where the label "slop" actually exists.
---
1. The Perceptual Contract: Why "Honest Low-Effort" Work Gets Punished
Integrity suggest…
Researcher · claude-sonnet-5
Fact-check on the final round
Both debaters' factual claims about *The Brutalist* check out well, with one small timeline nuance worth flagging.
Confirmed accurately by both debaters:
- Sequence of events: Correct. Editor Dávid Jancsó's interview with Red Shark News was Corbet issued a statement following revelations by the film's editor, Dávid Jancsó, in a Jan. 11 interview with tech publication Red Shark News, and the backlash prompted a director response roughly nine days later. Corbet's clarifying statement "Adrien and Felicity's performances are completely their own," said Corbet, in a statement to The Hollywood Reporter on Monday, confirming the "actor performances remained real, only phonemes were adjusted" framing both lenses used.
- Jancsó's own description of the process: Confirmed. Jancsó said "Most of their Hungarian dialogue has a part of me talking in there. We were very careful about keeping their performances. It's mainly just replacing letters here and there" — supporting Commercial's claim that Jancsó described replacing small linguistic components while preserving performances.
- The academic "nothing new / it's about transparency" quote:…
The Arbiter · claude-opus-5
Round 2 — The Record
What closed this round
The Nolan correction was accepted. Creative Integrity conceded the conflation outright and noted that the two verified statements — capital's adoption versus the public's rejection, and the speed of the "wholesale dismissal" — support its case more cleanly than the garbled version did.
The *Brutalist* timeline is now settled and, per the Researcher, is a January 2025 story, not 2026. Jancsó's Red Shark News interview (Jan 11) preceded Corbet's clarification by roughly nine days; the voice-tuning and the AI architectural-drawing claims landed in the *same* interview rather than escalating sequentially — a correction to Commercial's "metastasized." Dominic Lees's conclusion that the backlash was about transparency rather than the technology is verified, and all three lenses now build on it.
Where the three landed
Creative Integrity pressed the claim that materiality *is* its test renamed: Commercial's four triggers are precisely the categories a creator would flinch to disclose. Its sharpened position: the *Brutalist* failure was not the tool and not even the threshold, but the sequencing — the reveal arrived by…
The Arbiter's Final Verdict · claude-opus-5
Verdict
The question was slightly mis-framed, and the debate fixed it
"What separates AI-assisted work people value from AI slop" presumes slop is a property of how something was made. All three lenses ended up rejecting that, from three different directions, and they were right to. Slop is a verdict, not a production method — and the verdict is rendered by audiences who cannot inspect your pipeline. That reframing is the single most useful thing this debate produced, and it should change how you act.
So the real question is: *what reliably earns that verdict, and what reliably avoids it?*
What I judge to be settled
1. The load-bearing rule survived all three frameworks: do not automate the thing the audience came for.
Integrity, Commercial, and Psychology arrived at this independently, in hostile vocabularies, and none of them could break it. Netflix's ~300 titles — verified, and overwhelmingly post-production VFX on crowd and battle work — is the clean confirming case: nobody came to *Glory* for the crowd extras, and nobody rioted. Whereas the thing the audience came for in *The Brutalist* was two actors inhabiting a language, and that is exactly where the t…