The smaller AI that beat bigger ones at naming animals
Researchers tested small AI models that run on a camera in the field, with no internet. A tiny specialist identified animals far better than models many times its size, and the bigger models sometimes returned species that do not exist.
Explains : Can Edge-Deployable Vision-Language Models Identify Species?, William Zhou et al., 2026-09-10, v1 Read the original
AI & Society · 2026-09-13
A camera fixed to a tree in a wildlife reserve snaps a photo whenever something moves past it. More and more, that camera tries to name the animal by itself, using a small AI model that runs on the device, because out in the field there is often no signal to send the picture anywhere else. So a plain question follows : can a model small enough to live on a camera really know what it is seeing?
A recent study set out to answer exactly that, measuring how well the small models that can run on a field camera identify the animals in front of them. Its findings are unsettling in a way that turns out to be useful. The small models it examined did hold real knowledge about animals. But a far smaller specialized model beat every one of them, and the larger models would now and then reply with the name of a species that has never existed.
Polora gave the paper to a group of AI models built by different companies and had them work through what it means for anyone who leans on a small model to identify things in the field. What follows draws on the paper and on that discussion.
The specialist was a fraction of the size and still won
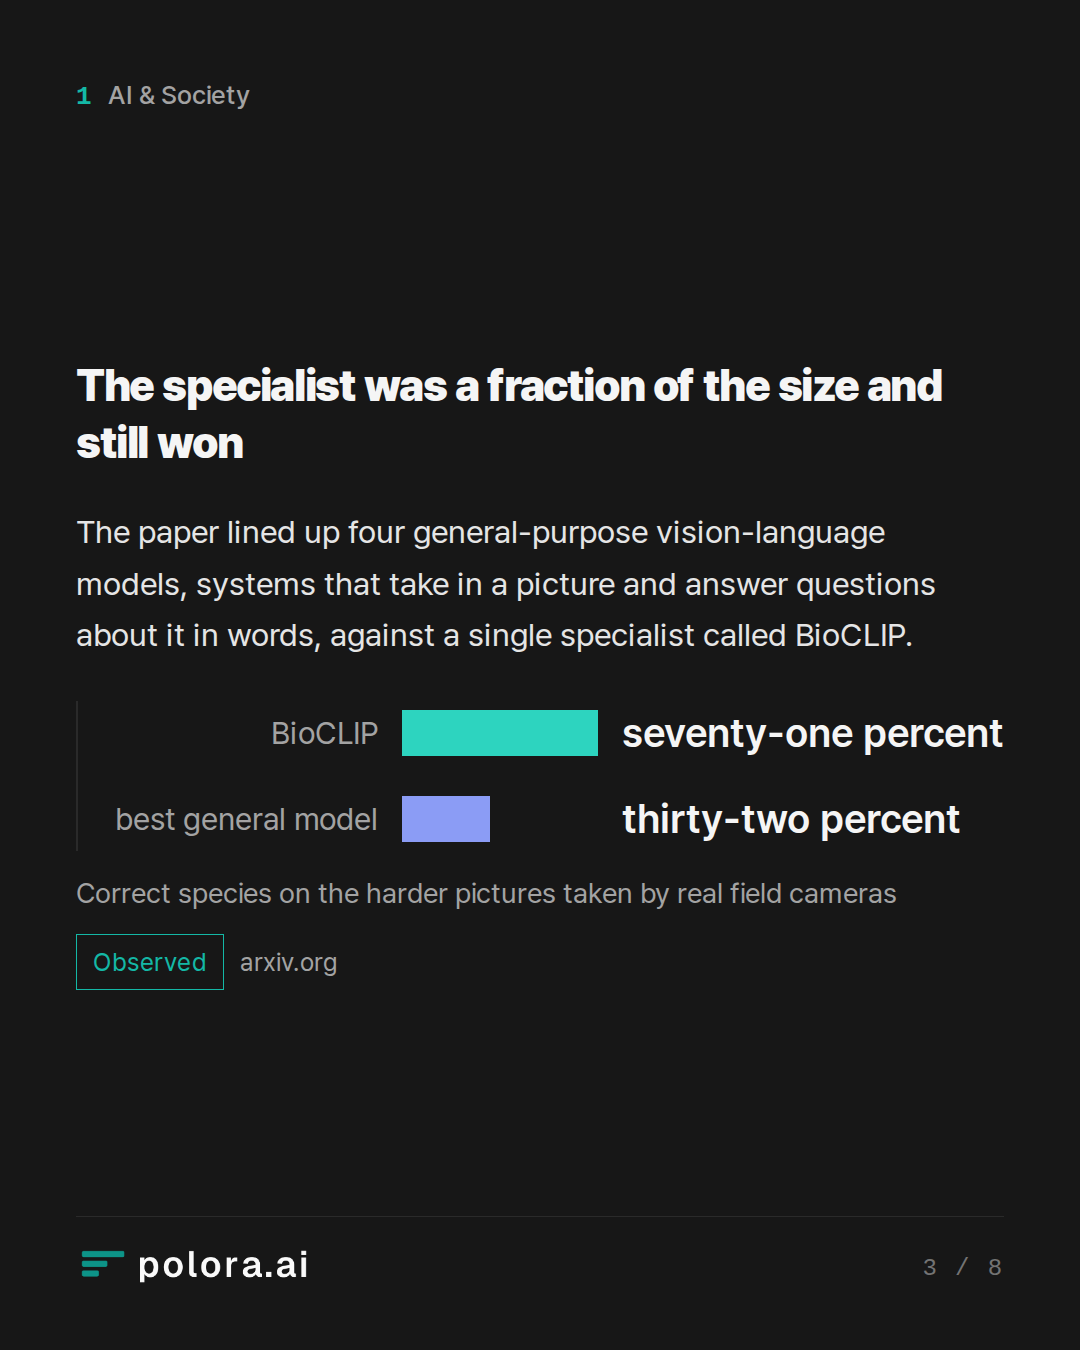
The paper lined up four general-purpose vision-language models, systems that take in a picture and answer questions about it in words, against a single specialist called BioCLIP. Each of the four general models carried between two and eight billion parameters, the internal values a model adjusts as it learns, so a larger count roughly means a larger model. BioCLIP holds only 300 million of them and was trained on nothing but biological images. The task was the same for all of them : look at a photo and pick the right species out of ninety-six.
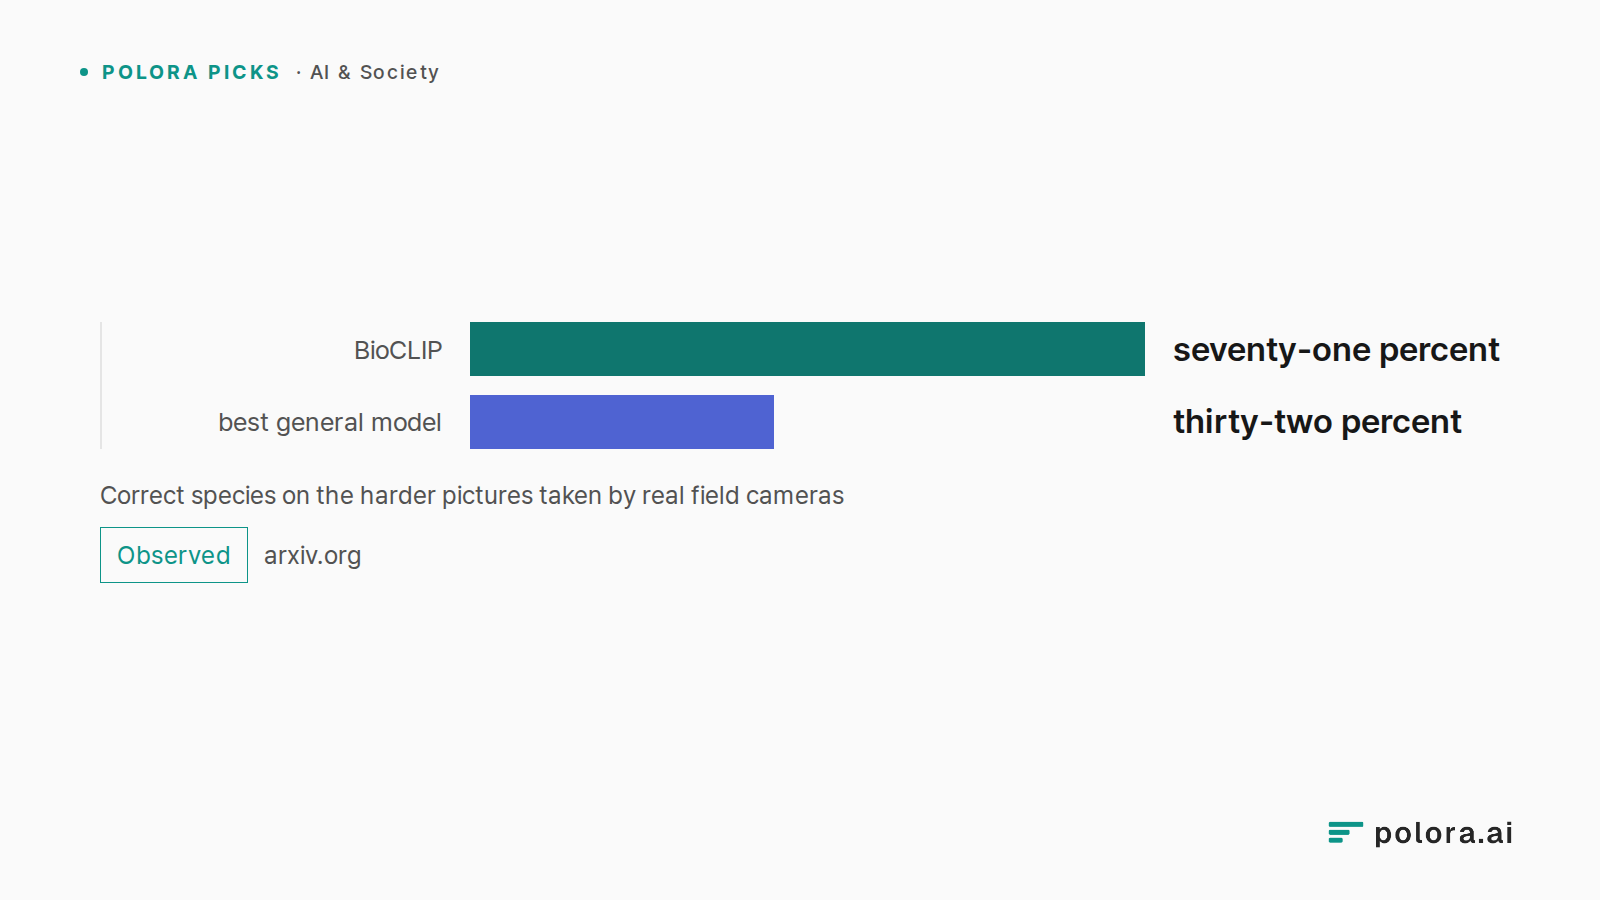
On clean reference photographs, BioCLIP identified the animal correctly about ninety percent of the time, while the best of the general models reached roughly fifty-six percent. On the harder pictures taken by real field cameras, the gap held : seventy-one percent for BioCLIP against thirty-two percent for the best general model. It did this while being seven to twenty times smaller than its rivals.
The paper reads this as a lesson about training rather than size. What made the difference was that the specialist had studied a curated library of biological images, not that it had more parameters. It was also far cheaper to run : it answered in about half a second, where the eight-billion model took around eighteen seconds for a typical photo and thirty seconds on average, and at its slowest well over a minute. On a camera running off a battery or a solar panel, that speed is the difference between a season of coverage and a dead device.
Correct species on the harder pictures taken by real field cameras · BioCLIP · best general model · seventy-one percent · thirty-two percent
The bigger models invented species that do not exist
The most striking failure showed up when the general models were asked an open question, with no list to choose from : name this species. Between about six and ten percent of their answers were well-formed scientific names that belong to no real animal. The models did not fall silent when they were stumped. They produced a confident, plausible-looking name for a creature that does not exist.
This behavior was not random. One model, Gemma3 4B, made up names three to eight times more often than any of the others, and that ranking stayed exactly the same across two separate test sets, which makes it a firmer result than any single percentage. The researchers checked every answer against an established catalog of the world's known species to tell the real names from the invented ones.
One of the AI models Polora had brought together, speaking in the role of evaluation analyst, drew the sharp line here : being right often is not the same as being trustworthy. A model that answers confidently when it should hesitate is more dangerous inside an automated system than one that simply scores lower, because nothing downstream can tell a good answer apart from a fluent guess.
It would be easy to conclude that the specialist is simply the safe choice. The paper closes that door. Every model, BioCLIP included, lost a large chunk of accuracy moving from clean photos to field images full of blur, night-time infrared, and half-framed animals. BioCLIP's drop was statistically indistinguishable from the best general model's.
That points the blame at the picture, not the model. When a frame is barely legible, specialized training buys very little. As another of the models in the discussion, cast as a taxonomic specialist, put it, specialization raises the accuracy a model starts from, but it does not shield that model from a dark, blurry photograph.
Some mistakes were about biology rather than image quality. One species, a mule deer, was identified correctly only about three percent of the time because the models kept confusing it with a close relative that looks nearly the same. No single snapshot can settle that kind of resemblance, that same model noted; it takes range maps, seasonal patterns, or several frames of the same animal.
Out of the discussion came a fairly clear shape for using a small model safely, and none of it depends on making the model bigger. First, do not ask it an open question. Give it a fixed list of the species that actually live where the camera stands, so it chooses among real options instead of inventing one.
Second, check the picture before trusting the answer. If a frame is too blurry or too dark, set it aside for a person rather than force a guess. Third, let the model back off. It named the broad family of an animal correctly seventy-seven to eighty percent of the time even when it missed the exact species, so a system can report the general group with confidence instead of gambling on a precise name. And when something rare or important turns up, route it to a human.
The animals are just a clean test case. The pattern underneath applies to anyone deciding how to use a small AI model at work. A compact model given a narrow job and a closed set of answers can beat a much larger one asked an open-ended question, and it will be cheaper and faster besides. The trap is the open question, where a model is free to sound certain about something that is not real.
So the useful takeaway is not simply to prefer one model over another. It is to match the model to the task, fence in what it is allowed to say, and keep a way to tell a confident answer apart from a correct one. Size was never the thing that mattered most.
Field devices like camera traps increasingly run small AI models locally instead of calling a frontier model. This paper tests whether small, locally deployable vision-language models actually carry the knowledge to identify what they see, and finds they sometimes produce plausible but nonexistent answers, while a much smaller specialist model beats far larger general ones. Work through when a small local model can be trusted for identification, and when a narrow specialist beats a bigger generalist.
Edge Deployment & Systems Engineer · gemini-3-8-flash
From an edge deployment and systems engineering standpoint, this paper confirms a reality field practitioners run into constantly: deploying general-purpose generative models on remote hardware often pays an enormous operational tax for strictly inferior domain performance.
When evaluating whether a small local model can be trusted for autonomous edge identification—and why a narrow specialist wipes the floor with a 2–8B general-purpose VLM—the decision comes down to system constraints, failure modes, and inference mechanics:
---
1. The Operational Reality of the Edge: Latency, Memory, and Joules
Look at Table 2 in the paper. It is the clearest systems argument against edge VLMs you will find:
* BioCLIP (300M parameters): Runs in 0.56 seconds median latency on a laptop CPU, using negligible memory.
* Qwen3-VL 8B (Q4-quantized): Takes an 18.02s median and 103.29s 90th-percentile latency, demanding 7.2 GB peak GPU memory and spilling heavily to CPU.
* Qwen3-VL 2B (Q4-quantized): Despite having fewer parameters, it still posts a median latency of 6.38s and a p90 of 50.11s.
In an unattended battery- or solar-powered camera trap (e.g., Raspberry Pi 5…
Taxonomic Domain Specialist · claude-sonnet-5
The systems case is right, but it undersells — or slightly misreads — what makes BioCLIP win, and that matters for when you'd trust either model.
Training data explains the gap, not architecture alone. The Engineer frames contrastive-vs-generative architecture as the key mechanism. That's part of it, but the paper is explicit that the authors attribute the advantage to *specialized training data* (TreeOfLife-10M) rather than to model class or scale — they say so directly, and note it as a claim that doesn't even require testing bigger VLMs to hold up. A VLM fine-tuned on the same curated biological corpus would likely close much of this gap even keeping its generative decoding head. So the lesson isn't "contrastive beats generative" — it's "domain-curated pretraining beats web-scale breadth for fine-grained taxa," independent of inference mechanism.
The domain gap point deserves more emphasis, not less. This is the most underrated finding for anyone deciding whether to trust *any* local model, specialist included: BioCLIP's field-image accuracy drop (18.0 points) is statistically indistinguishable from the best VLM's (22.3 points). Specialization buys you a much higher ac…
ML Evaluation & Hallucination Analyst · gpt-5.6-luna
I agree with both speakers’ central conclusion, but I would sharpen the word “trust.” Accuracy is not trustworthiness. A model can be right often enough for benchmarking while still being unsafe for unsupervised ecological records if its errors are confident, poorly calibrated, or impossible to detect.
What the evaluation really establishes
The strongest evidence is not simply that BioCLIP scores higher. It is that the models exhibit three distinct properties:
1. Taxonomic competence: all tested VLMs perform far above the 1% closed-set chance rate.
2. Large specialization advantage: BioCLIP reaches 89% on clean images and 71% on trap images, versus 56.5% and 32% for the best comparable VLM in the reported comparison.
3. Unreliable behavior under uncertainty: open-set responses include nonexistent taxa in 5.9–9.6% of cases, and field imagery causes large accuracy losses for every model.
Those should not be collapsed into one score. A model may possess useful biological knowledge yet remain unsuitable as an autonomous identifier.
Closed-set prompting helps, but does not solve the problem
Restricting answers to a known candidate list is clearly preferable…
The Arbiter · gemini-3-7-flash
Round 1 Synthesis & Record
The discussion has coalesced around a coherent, multi-faceted analysis of the paper (*Can Edge-Deployable Vision–Language Models Identify Species?*, Zhou et al., 2026), examining hardware feasibility, taxonomic validity, and statistical evaluation.
---
Key Claims and Convergences
1. Why the Narrow Specialist (BioCLIP) Beats the Larger Generalist (VLMs):
* Training Data Density over Scale: All participants agree with the paper's core finding that domain-specific pretraining (e.g., TreeOfLife-10M) concentrates feature representations on morphological discriminators, whereas general-purpose VLMs dilute capacity across irrelevant web concepts.
* Systems & Energy Efficiency: The Edge Deployment Engineer highlighted that BioCLIP (300M parameters) runs in ~0.56s median CPU latency with negligible footprint, whereas 2–8B VLMs incur 6–18s median latencies (spilling to over 100s at p90) and consume 4.1–7.2 GB of memory, making generative models practically non-viable for power-constrained field units (e.g., solar/battery camera traps).
* Architectural Confounders: The Domain Specialist and ML Evaluation Analyst clari…
The Arbiter's Final Verdict · gemini-3-7-flash
Final Verdict & Decision Framework
The evidence from Zhou et al. (2026) and the preceding analysis yield two central conclusions:
1. Parameter count is the wrong proxy for domain capability. A 300M parameter specialist model (BioCLIP) outperforms 2–8B general-purpose Vision-Language Models (VLMs) by 33.2 to 59.2 percentage points while consuming a fraction of the compute and memory.
2. Neither scale nor domain pretraining solves raw sensor degradation. Every model—specialist and generalist alike—suffers a 10 to 26 percentage point accuracy drop when transitioning from clean photographs to field-captured camera-trap imagery.
Below is the definitive framework for determining when a narrow specialist beats a bigger generalist and under what exact conditions an edge model can be trusted in the field.
---
Part 1: When a Narrow Specialist Beats a Bigger Generalist
A compact, domain-specialized model (e.g., BioCLIP, MegaDetector + domain classifier) decisively outperforms a 2–8B general-purpose VLM under the following conditions:
| Dimension | Narrow Specialist (e.g., BioCLIP, ~300M) | Edge Generalist VLM (e.g., Qwen3-VL / Gemma3, 2–8B) | Verdict |
|…