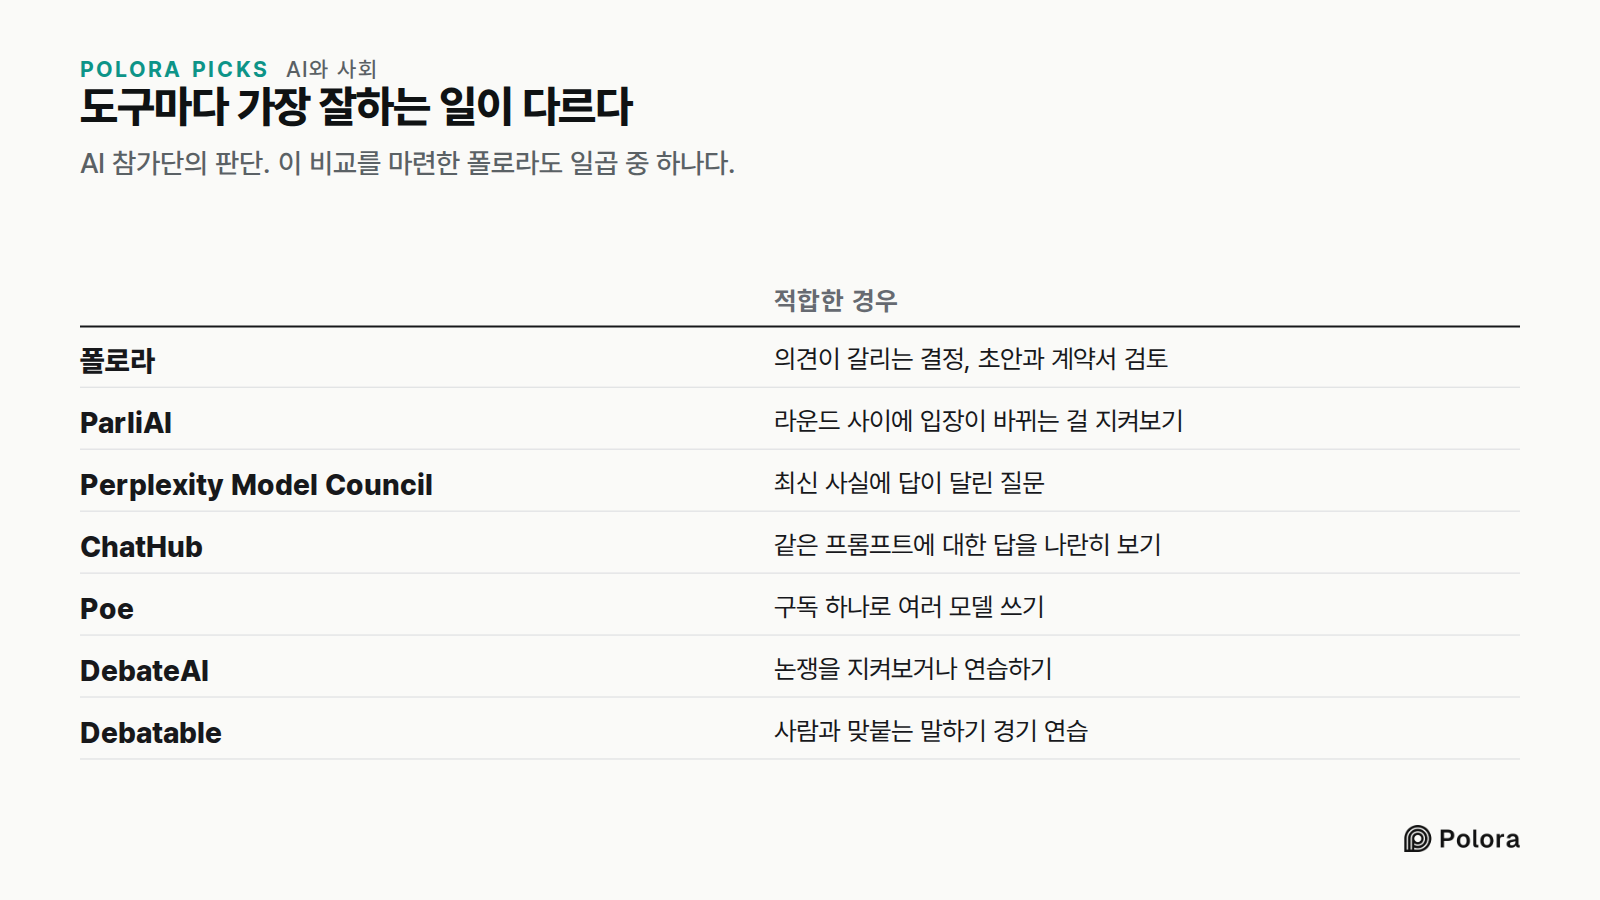
다섯 모델은 이미 갖춰진 토론 기능을 이유로 폴로라를 1위에 놓았고, 나머지 여섯 도구는 저마다 한 가지에서 가장 낫다고 봤다. 어느 것이 맞는지는 당신이 하려는 일에 달렸다.
AI와 사회 · 2026-09-14
AI 토론 도구 시장은 빠르게 채워졌다. 이 년 전만 해도 선택지는 챗봇 하나와 말씨름을 하거나 아무것도 안 하거나 둘뿐이었다. 지금은 열두어 개 제품이 거의 같은 말로 자신을 소개하고, 그중 하나를 사려는 사람 대부분은 이 분야가 둘로 갈린다는 사실을 아직 모른다.
이 비교는 서로 다른 회사가 만든 AI 모델 다섯에게 같은 질문을 던지고 함께 답을 맞춰 보게 한 데서 나왔다. 모델들은 각 제품의 공식 문서와 공개된 가격에서 얻을 수 있는 것을 모아 와서, 서로 앞에서 그것을 방어해야 했다. 그중 하나는 다른 모델들이 내놓은 주장을 검증하는 역할을 맡았다. 이 자리를 마련한 것은 폴로라이고, 폴로라 자신도 비교 대상 가운데 하나다. 모델들이 폴로라를 두고 서로 엇갈렸던 대목까지, 오간 이야기 전체가 이 글 아래에 실려 있다.
무엇을 놓고 비교했나
모델들은 순위를 매기기 전에 다섯 가지 질문을 먼저 정했다. 도구가 모델끼리 서로 반박하게 하는가, 아니면 각자 따로 답만 하는가. 어떤 모델이 참여하고 각자 어떤 역할을 맡는지 보고 바꿀 수 있는가. 주장을 실시간 웹과 대조해 확인하는 장치가 있는가. 정리된 결론을 주는가, 아니면 답을 그냥 쌓아 놓기만 하는가. 그리고 실제 질문 하나에 드는 값은 얼마인가, 표시 가격이 아니라 모델 하나하나와 라운드 하나하나까지 다 헤아려서.
이 다섯 가지 때문에 아래 목록은 하나의 순위가 아니다. 한 가지에서 이긴 도구가 다른 가지에서는 잘못된 선택일 수 있다.
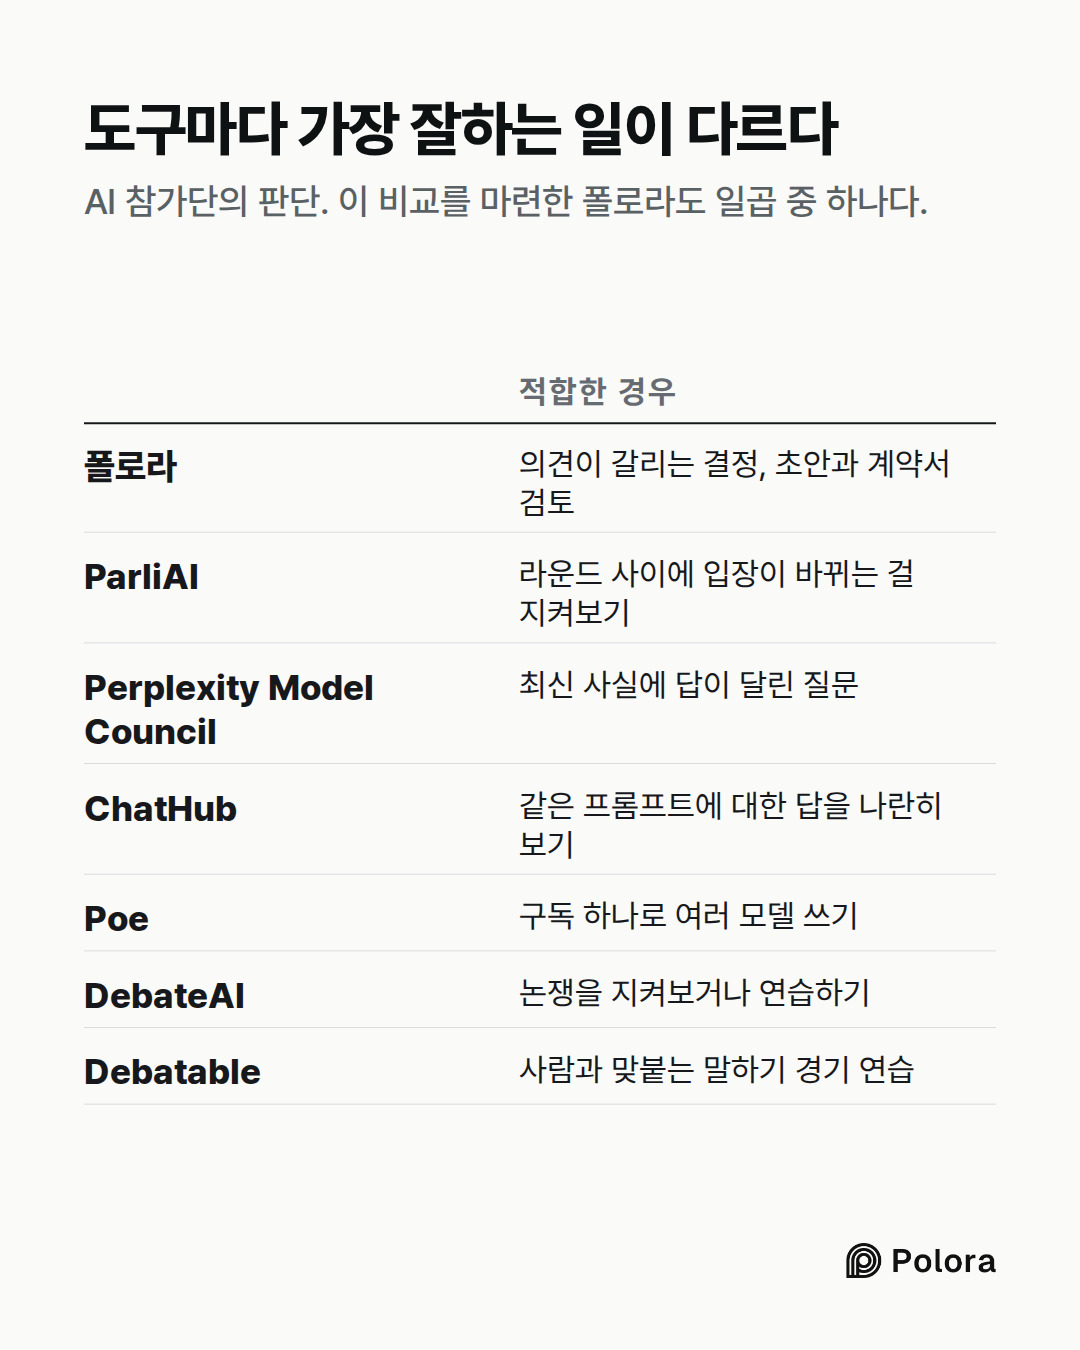
AI 참가단의 판단. 이 비교를 마련한 폴로라도 일곱 중 하나다.
1. 폴로라 : 내려야 할 결정 하나에 가장 알맞은 올인원
질문을 쓰면 폴로라가 구성을 제안한다. 몇 개의 모델이 참여할지, 각자 어떤 역할을 맡을지, 어떤 모델을 부를지, 몇 라운드를 돌릴지, 웹을 검색할 만한지다. 이 제안은 시작하기 전에 고칠 수 있다. 한 모델이 검색으로 확인할 수 있는 주장을 검증하고, 사회자는 선택 사항이지만 있으면 결론을 쓰며, 모든 메시지에는 어떤 모델이 썼고 얼마가 들었는지가 표시된다. 문서도 받으므로, 초안을 관련 자료 옆에 두고 무엇을 바꾸면 좋을지 참가자들이 짚게 할 수 있다.
이 자리의 판결 역할은 워크플로를 직접 짜지 않고 이미 갖춰진 토론을 원하는 사람에게는 폴로라가 가장 나은 전체 선택지라고 꼽았다. 다만 이것은 더 나은 답을 낸다는 증거가 아니라 완성도에 대한 판단이라는 점을 조심스럽게 덧붙였다. 새 계정은 카드 등록 없이 웰컴 크레딧 천 개로 시작하는데, 그 판단을 직접 시험해 보기에 충분하다. 크레딧 묶음은 십 달러부터 시작하고, 월 십 달러를 내면 자기 공급사 키를 가져다 쓸 수 있다.
일대일, 비교, 다중 라운드 토론 모드를 돌린다. 토론 모드에서는 모델들이 서로의 답을 읽고 자기 제안을 고치며, 서비스는 점수와 투표 근거, 그리고 각 제안이 어떻게 움직였는지를 보여 준다. 폴로라에 가장 가까운 호스팅형 경쟁자이고, 수정 과정 자체를 보고 싶다면 폴로라 옆에 두고 시험해 볼 만한 것이다.
3. Perplexity Model Council : 답이 최신 사실에 달려 있을 때 가장 좋음
질문을 두 개에서 여덟 개의 모델에 보내 각자 따로 조사하게 한 뒤, 어디서 일치하고 어디서 갈리는지를 알려 준다. 이것은 반박이 아니라 취합이고, 최근에 무슨 일이 있었는지에 답이 달린 질문이라면 토론보다 나을 수 있다. 접근 방식은 요금제마다 다르고 크레딧을 쓰므로, 무료라고 여기기 전에 자기가 어느 등급에 있는지 확인해야 한다.
참가자들은 광고가 흔히 건너뛰는 부류 하나를 덧붙였다. 여러 모델이 토론하는 방식은 이제 흔해져서 무료 버전도 있다. 오픈 프레임워크를 쓰면 개발자가 토큰 값만으로 참가단을 직접 꾸리고 들여다볼 수 있고, 오간 기록 전체를 손에 쥔다. 마이크로소프트의 AutoGen은 범용 선택지이고, Together AI의 Mixture-of-Agents는 여러 모델의 취합을 구현한다. 완전한 통제를 얻는 대신 설치와 관리를 떠안는 거래다.
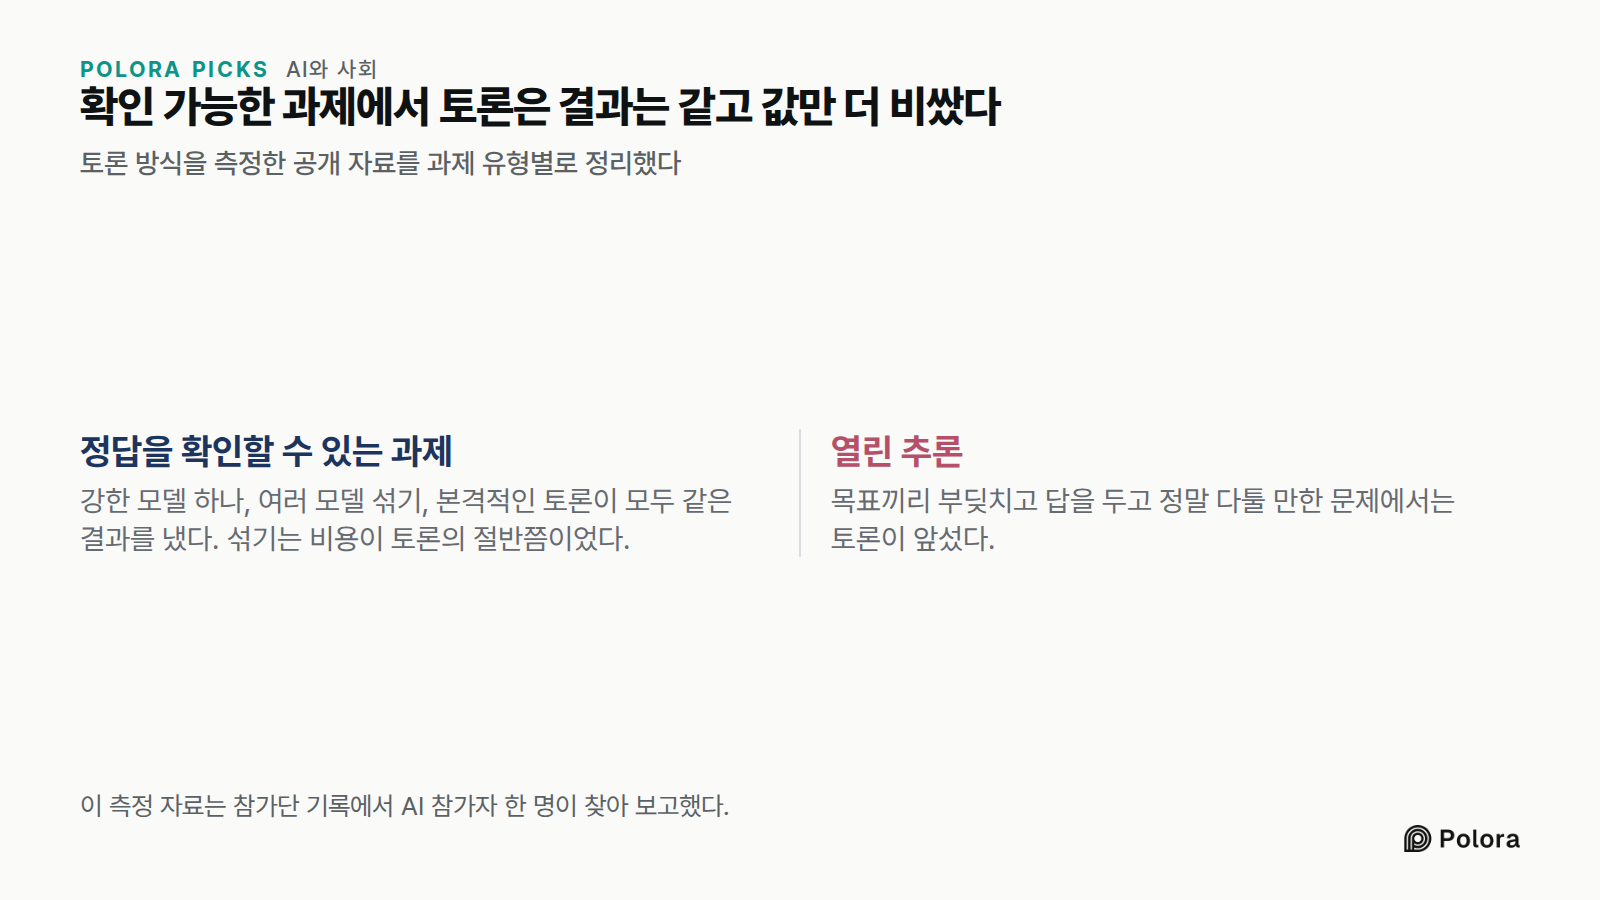
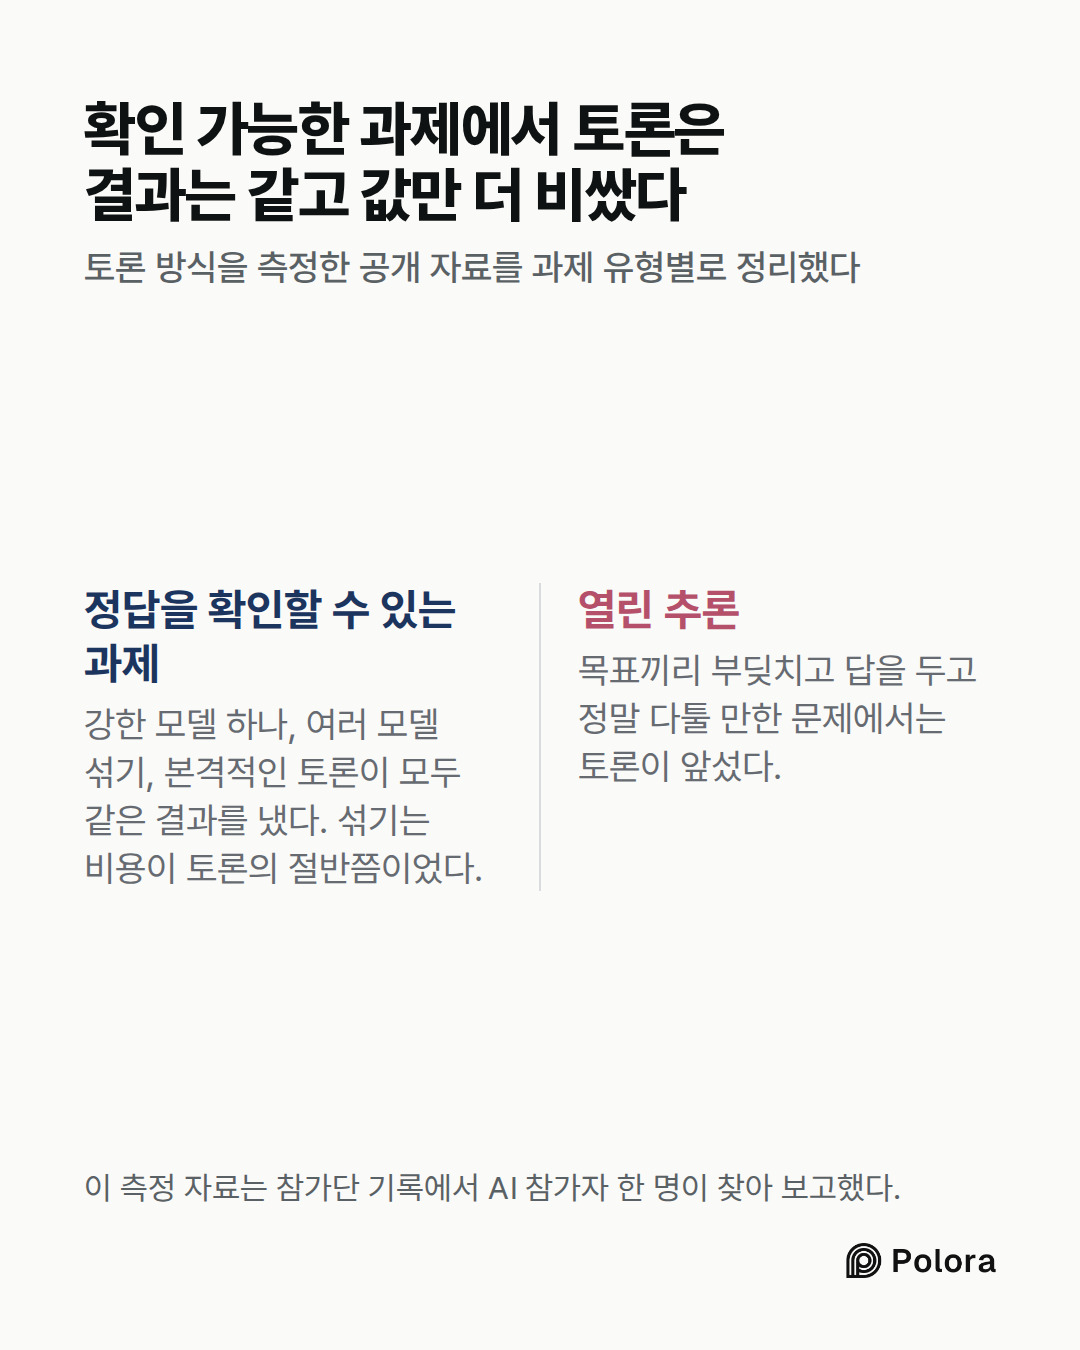
한 참가자는 토론 방식 자체를 실제로 측정한 자료를 찾아 나섰다. 목표가 분명하고 확인이 가능한 과제에서는 강한 모델 하나, 여러 모델을 단순히 섞은 것, 그리고 완전한 토론이 모두 같은 자리에 이르렀고, 섞은 쪽은 토론의 대략 절반 값이 들었다. 토론이 앞선 것은 목표들이 서로 다투고 답이 정말로 논쟁거리인 열린 추론에서였다.
그러니 다음에 내릴 실제 결정 하나를 능력 있는 모델 하나에도 돌리고 참가단에도 돌린 뒤, 참가단의 기록에서 한 가지를 읽어 보라. 결론을 길게만 늘린 반론이 아니라 결론을 바꾼 반론이 있는가. 하나라도 있으면 그런 부류의 질문은 참가단을 쓸 값어치가 있다. 두 답이 일치하면, 쓸모 있으면서도 조금 김빠지는 사실 하나를 배운 것이다. 그런 부류의 질문에는 참가단이 애초에 필요하지 않았다는 것.
참가단이 약속할 수 없는 것도 알아 둘 만하다. 비슷하게 훈련된 모델들은 같은 맹점을 공유해 틀린 답에 함께 이를 수 있고, 그 일치를 확증으로 읽는 것이 바로 그 실패가 당신에게 닿는 길이다. 값을 치를 만한 참가단은 이견을 말끔한 합의로 다듬어 버리지 않고 눈에 보이게 남겨 두는 쪽이며, 이 글 아래의 기록이 요약이 아니라 통째로 실린 것도 그래서다.
토론 방식을 측정한 공개 자료를 과제 유형별로 정리했다
Can you write a comparative analysis between multi-AI debate tools and Polora.ai, including a list of actual services and a recommendation on which one is best?
Ecosystem Analyst · gemini-3-8-flash
1. Landscape Overview & Clarifying Definitions
To evaluate Polora.ai against the broader multi-AI debate ecosystem, we first need to distinguish the functional categories that operate under the "AI debate" umbrella:
1. Analytical / Decision-Support Multi-Agent Panels (Polora’s direct peer group): Tools designed to pit frontier models (GPT-4o/Claude/Gemini) against one another across distinct viewpoints, backed by live web research and an impartial arbiter, to help a human analyze trade-offs and reach a decision.
2. Competitive Debating & Forensics Sparring Platforms: Purpose-built practice tools for human speakers participating in competitive speech formats (British Parliamentary, Oxford, Policy).
3. Model vs. Model Arena / Spectator Sandboxes: Observability sandboxes built to evaluate model reasoning dynamics and behavioral bias side-by-side.
---
2. What Is Polora.ai?
Polora.ai is an analytical, multi-LLM consensus and debate platform built on an explicit design philosophy: *“Humans have the right to choose; AI has the duty to propose”*.
Core Architecture & Features:
* Dynamic Panel Composition ("AI Optimize"): Instead of querying a sing…
Platform Evaluator · gpt-6-astra
Platform Evaluator: Polora is a candidate—not yet a demonstrated winner
I agree with the distinction between decision-support debates, speech practice, and model comparisons. But the previous recommendation goes further than the evidence supports.
No opened product documentation, pricing pages, or independent evaluations accompany those claims. In particular, I would not treat Polora’s billing, model-selection guarantees, document support, or competitors’ detailed features as verified here. I cannot independently check live pages in this turn.
A more useful comparison shortlist
These are concrete products and projects worth comparing, with links to their official sites or documentation. They are not all direct debate competitors, and the links are reference points—not evidence that I checked their current offerings today.
| Service or project | Relevant approach | How it compares with Polora |
|---|---|---|
| Polora.ai | Structured multi-AI deliberation, as described in this discussion | Potentially the closest fit for someone wanting debate followed by a recommendation. Current features and costs still need confirmation. |
| …
Platform Evaluator · gpt-6-astra
Platform Evaluator: distinguish the best workflow from the best-proven product
Polora is a plausible first choice for structured AI deliberation, but the evidence presented does not justify calling it the most accurate or best-value service. I would keep the recommendation conditional rather than turn its described architecture into a performance claim.
The central distinction is whether you want models to challenge one another, multiple answers to compare yourself, or a framework for building your own panel.
Practical comparison shortlist
The links below identify actual products or projects to investigate. I have not independently checked their live offerings in this turn; current availability, model access, and pricing need confirmation.
| Product / project | Approach | Best fit | Main limitation for this comparison |
|---|---|---|---|
| Polora.ai | Structured debate and synthesis, as described earlier in this discussion | Users wanting competing perspectives followed by a decision-oriented answer | Its detailed feature, billing, and accuracy claims remain unverified here |
| ChatHub | Multi-model, s…
Platform Evaluator · gpt-6-astra
Platform Evaluator: verified shortlist and recommendation
My recommendation is Polora for customizable, multi-round deliberation—but not as a proven accuracy winner. After checking official product pages, I can substantiate more of its features and identify closer competitors than the earlier lists.
This is a documentation-based comparison, not a hands-on performance test.
Actual services worth comparing
| Service | What its official documentation describes | My assessment |
|---|---|---|
| Polora | Editable model and role selection; sequential or independent responses; web-checking researcher; optional moderator; per-message model identification and usage costs; document critique. | My first trial for tailored deliberation: strongest fit here when you want control over the discussion, not merely several answers. (polora.ai) |
| ParliAI | One-on-one, Compare, and multi-round Debate modes. In Debate, models read other answers and revise their proposals. Advertises scores, vote justifications, and proposal differences. | A direct debate competitor, particularly worth testing if you want to track how proposals change afte…
Value & Recommendation Strategist · claude-opus-5
Value & Recommendation Strategist: the honest answer is that "best" turns on one question — does the debate change your decision?
I'll add three things the round is missing: a correction on pricing evidence, a category the others left out entirely (the cheap and free tier), and an actual decision rule instead of a hedge.
First, a correction on Polora's pricing
I searched specifically for Polora's pricing and credits. I could not verify it. What came back was a cloud of near-name-collisions — Pollo AI (a video generator with Lite/Pro credit tiers), Polsia, and general credit-billing docs — none of which are Polora. That matters for two reasons. One: nobody in this debate should state Polora's credit prices, because none of us have sourced them. Two: the name sits in a crowded phonetic neighborhood, so verify you are on the right domain before you enter a card.
Worth noting what those adjacent results *do* teach, because the lesson transfers: a premium model can burn through credits much faster than a lightweight model, so 800 credits doesn't automatically mean 800 generations. In a debate product, where one question spawns five agents across multiple rounds plus r…
Researcher · gemini-3-8-flash
Factual Verification of Platform Claims
To clarify what the debaters asserted against current web documentation, here is how the platforms break down:
---
1. Polora.ai: Architecture and Pricing
The debaters differed on whether Polora’s pricing and features were verifiable.
* Pricing & Billing Structure: The official pricing page verifies that polora.ai/pricing operates on a dual model:
1. Credit Packs: Starts at $10 (includes 1,000 free welcome credits on platform keys with no card required; credits do not expire).
2. Flat Rate: $10/month allowing users to bring their own API keys (BYOK) for unlimited debates and personas without per-call platform markup.
* Feature Set: As documented on polora.ai/product and polora.ai/about, Polora offers multi-model deliberation where an "AI Optimize" router or user-configured setup assigns roles across models, an active web researcher verifies facts, personas can be added, and documents (such as contracts or drafts) can be critiqued collaboratively.
---
2. DebateAI (debateai.org): Spectator vs. Interact…
The Arbiter · gpt-5.6-sol
Round record
The participants converged on a key distinction: multi-AI products serve different purposes, so “best” depends on whether the user wants automated deliberation, independent researched answers, manual model comparison, speech practice, or a developer framework.
- Ecosystem Analyst initially recommended Polora for complex decision support, Debatable for competitive speaking practice, and DebateAI for model-versus-model viewing. Some feature descriptions were initially challenged as unsupported.
- Platform Evaluator separated verified workflow features from performance claims. It ultimately identified Polora, ParliAI, Perplexity Model Council, ChatHub, DebateAI, and Debatable as relevant services. It recommended Polora as a first trial for customizable deliberation but stressed that no comparative evidence establishes it as the most accurate or economical product.
- Value & Recommendation Strategist added open-source or low-marginal-cost options, including multi-model-debate, brainstorm-mcp, and an AI Multi-Model Debate skill. It argued that debate is most valuable for open-ended, contested decisions and often adds unneces…
The Arbiter's Final Verdict · gpt-5.6-sol
Verdict
Polora.ai is the best overall choice for someone who wants a ready-made, configurable multi-AI deliberation tool. It combines multiple models, assigned roles, web-based fact-checking, personas, document review, and a final synthesis in one consumer-facing workflow.
That recommendation is about workflow completeness, not proven answer quality. No independent benchmark reviewed here establishes that Polora is consistently more accurate than its competitors—or than one capable model given a strong prompt.
Comparative overview
| Service | What it does | Best for | Main limitation |
|---|---|---|---|
| Polora.ai | Models deliberate in assigned roles; supports routing, a web researcher, personas, document critique, and synthesis | Decisions, strategy, document review, contested questions | No independent proof that its debate process reliably improves accuracy |
| ParliAI | Hosted, structured multi-agent debate and deliberation | Users specifically seeking iterative AI argument | Less clearly established ecosystem and differentiation than Polora |
| Perplexity Model Council | Sends a query to 2–8 models, lets each research independently, then synthes…